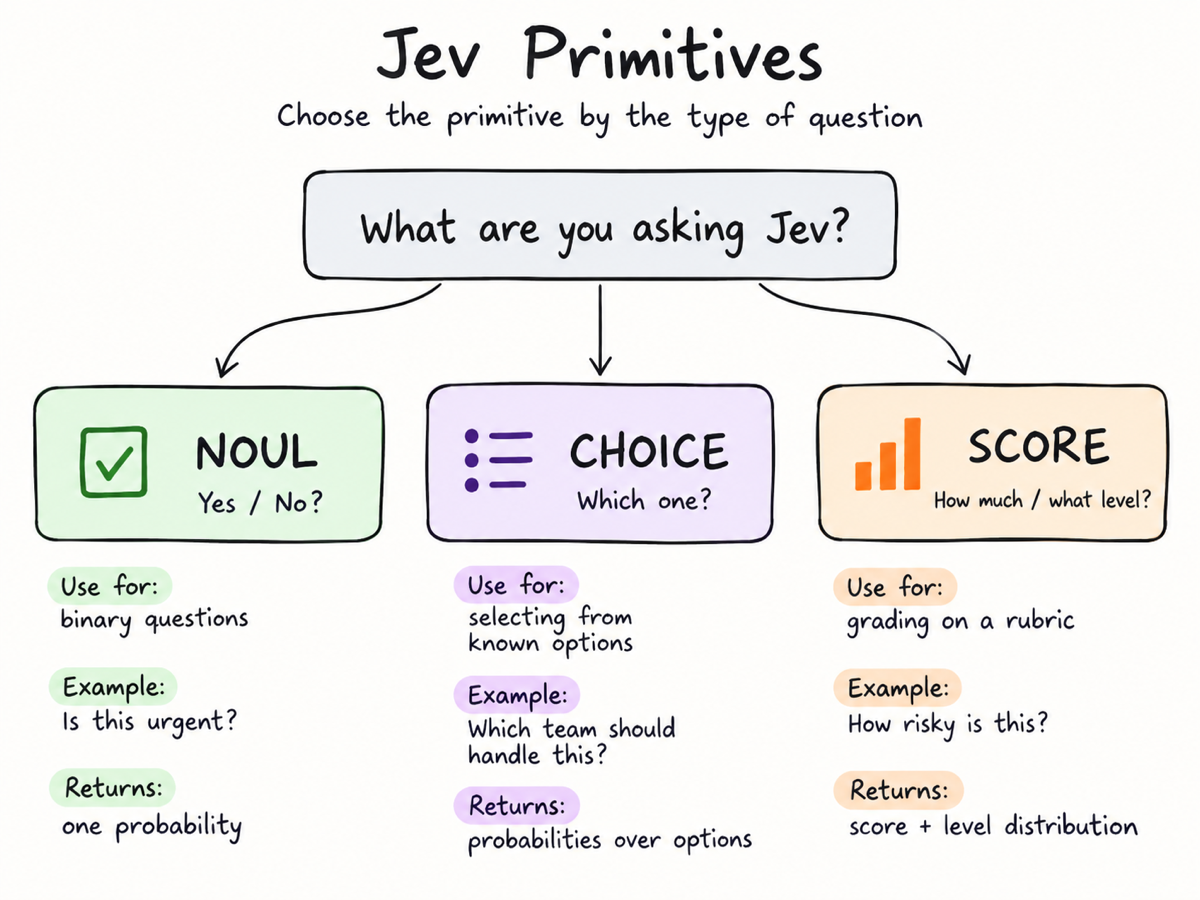
classifier.dev benchmarks tiered classification against Jev
classifier.dev announced benchmark results across public datasets like AG News and Emotion, showcasing how its dual-tier architecture achieves high accuracy and throughput. Its fast tier uses TypeSafe's Jev decision model to classify batches of up to a thousand inputs in milliseconds, while its smart tier automatically re-routes uncertain predictions (confidence below 0.7) to Gemini 3.8 Flash for reasoning-based re-evaluation, achieving up to 90% accuracy on AG News while keeping latency and costs amortized.
Tiered classification with selective escalation is the smartest path forward for text processing, allowing developers to filter noisy data streams cheaply without wasting precious LLM context tokens.
• Cost and context efficiency: Offloading high-volume tasks like log filtering, search pruning, and issue routing to specialized decision models prevents token bloat and reduces inference costs.
• Effective selective escalation: Instead of paying full frontier latency and pricing on every sample, escalating only low-confidence items (<0.7) captures accuracy improvements where they matter most.
• Agent-first developer ergonomics: Offering plain HTTP endpoints, streaming shell pipelines, and native MCP tools enables seamless integration directly into agentic workflows and developer pipelines.
• Benchmark realism: While the calibration metrics and throughput numbers are strong, the public datasets evaluated are likely present in upstream pretraining corpora, meaning custom benchmarks remain essential for domain-specific production use.
DISCOVERED
1h ago
2026-09-20
PUBLISHED
1h ago
2026-09-20
RELEVANCE
AUTHOR
michael_chomsky