OPEN LINK ↗
// 40m agoBENCHMARK RESULT
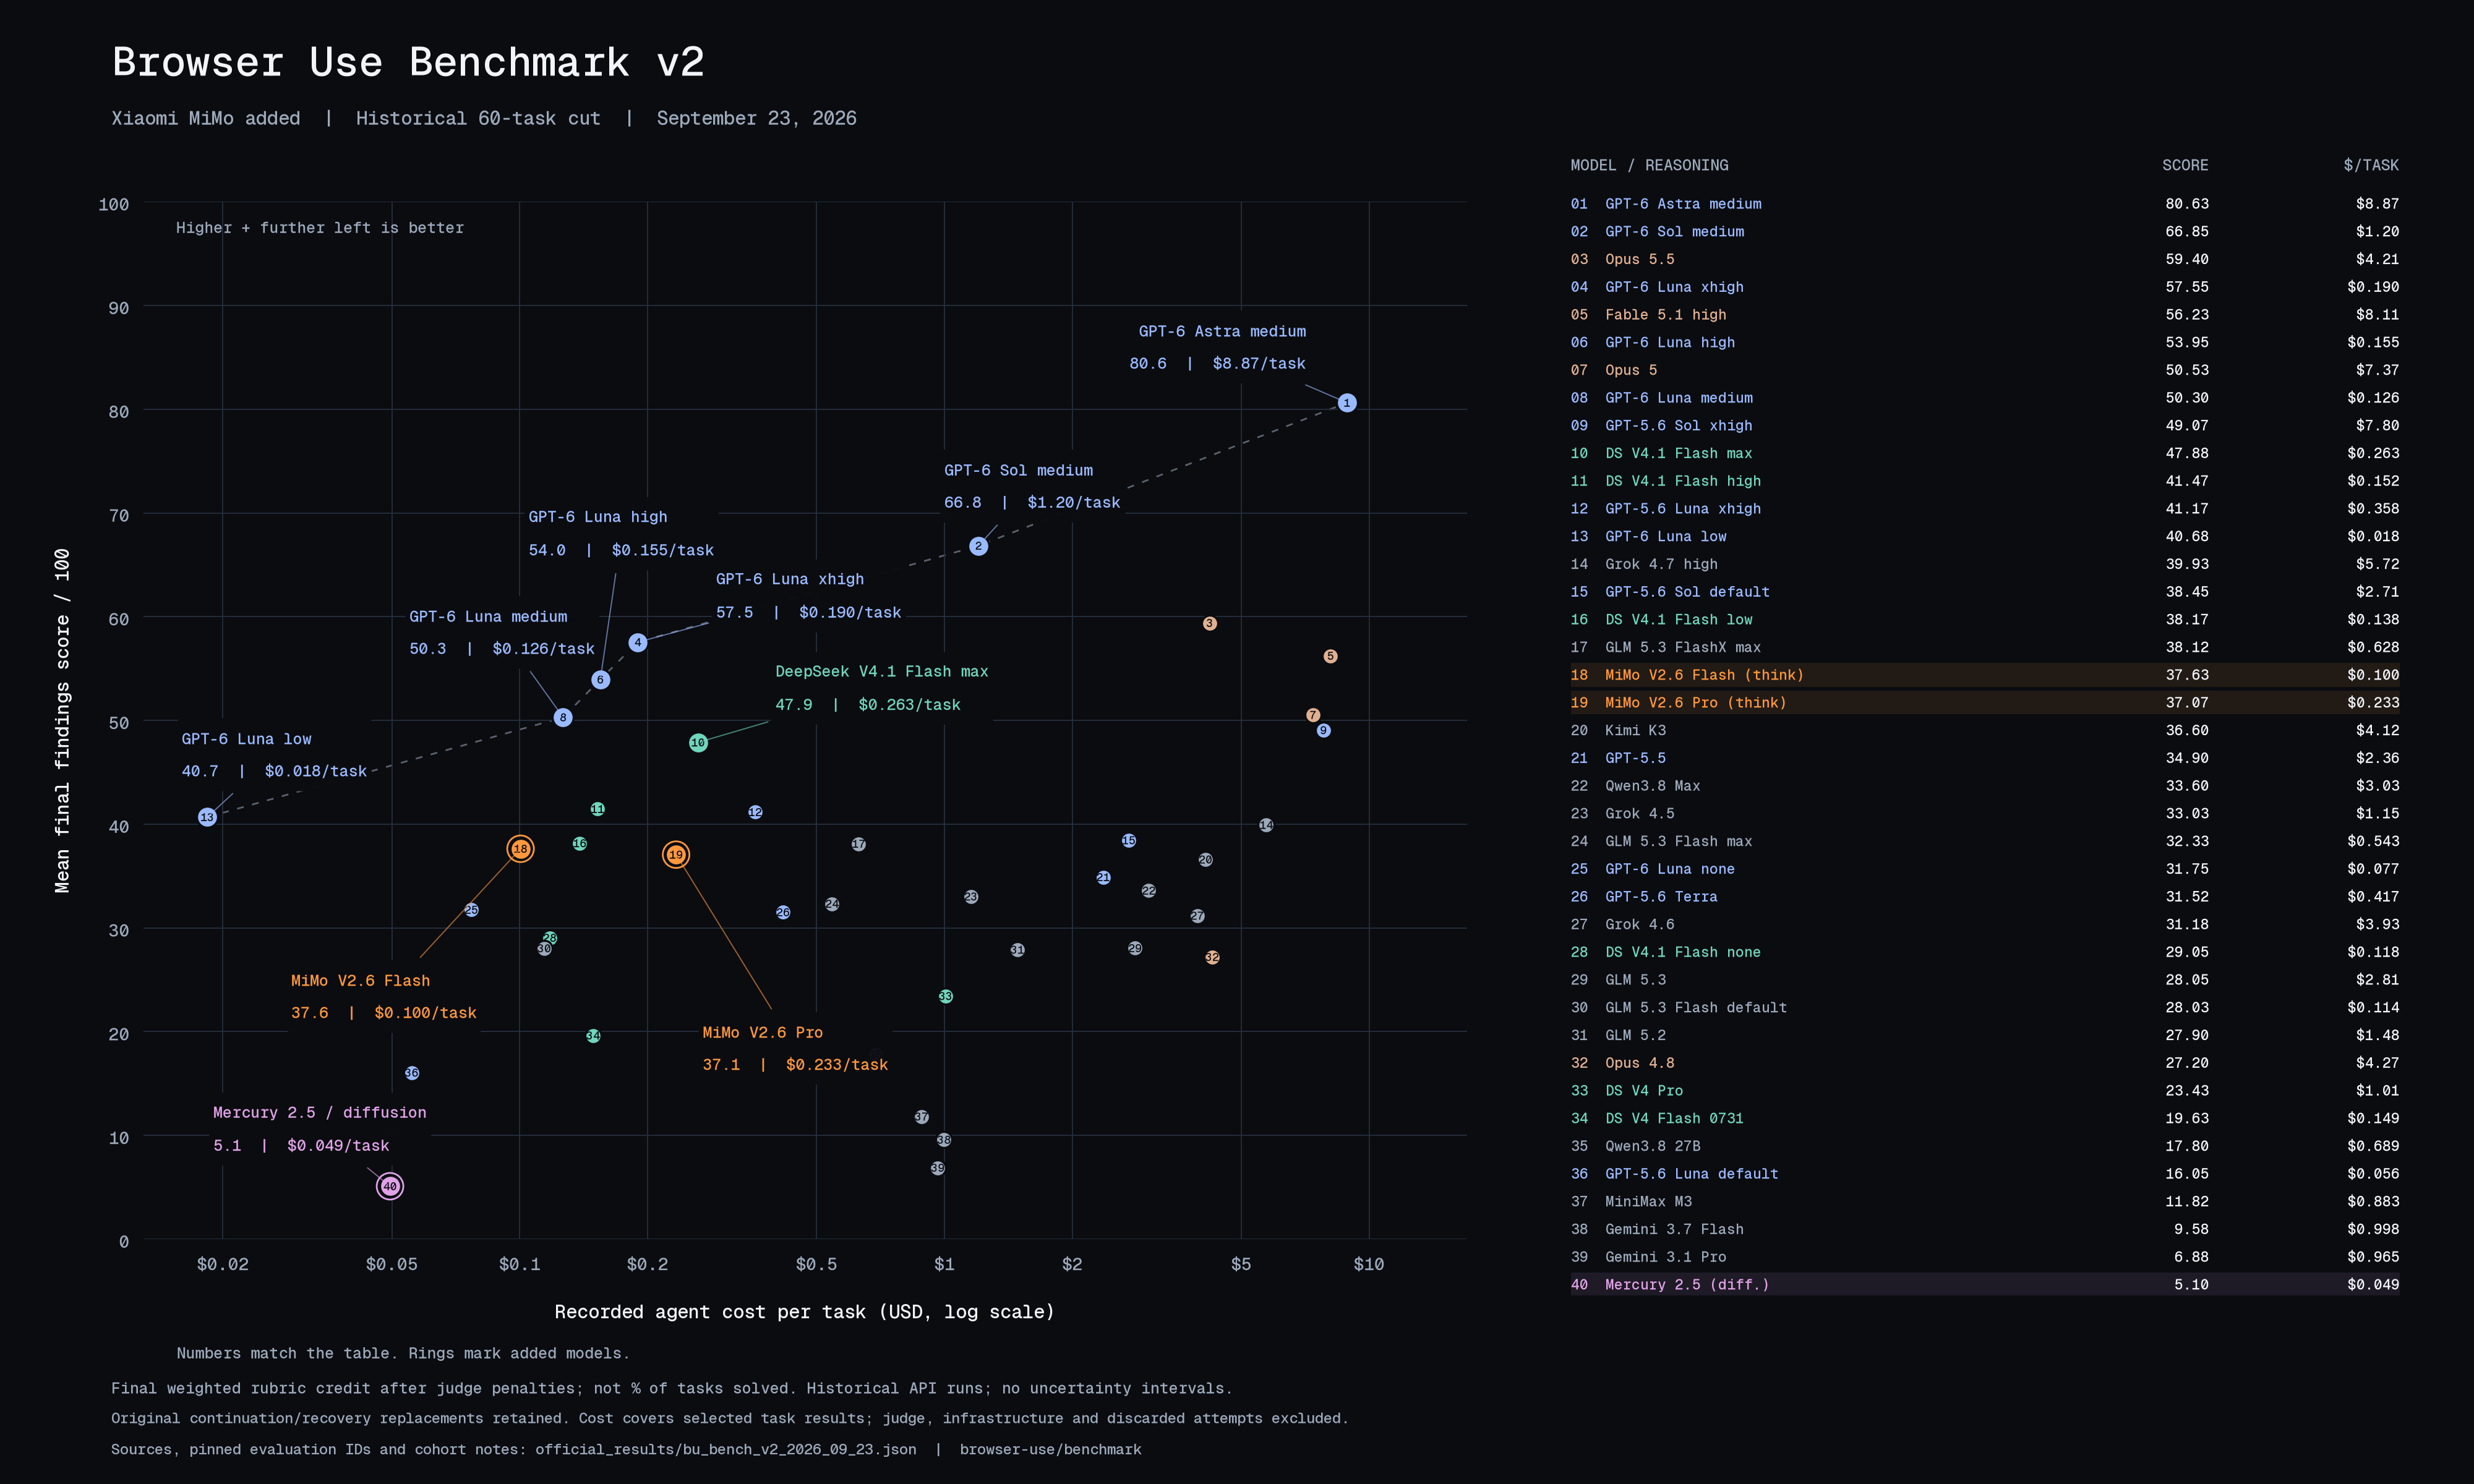
Browser Use Benchmark Tests Seven Harnesses
Browser Use compares seven browser harnesses on 200 difficult, long-horizon web tasks using the same GPT-6.1 Terra medium model, task set, and judge, isolating harness design as a major variable in agent performance. See the benchmark repository at https://github.com/browser-use/benchmark.
// ANALYSIS
The hot take: browser agents are complete systems, not interchangeable model wrappers.
- –Fixed models and judges make score differences meaningful evidence about orchestration quality.
- –Observation formats, tool design, action loops, retries, and context management can determine whether long tasks survive.
- –Long-horizon evaluation is more revealing than polished browser demos or short navigation tests.
- –Developers should benchmark the full stack—including latency, token usage, recovery, and browser reliability—not models alone.
// TAGS
browser-usebenchmarkevaluationweb-agentcomputer-useagent
DISCOVERED
40m ago
2026-11-13
PUBLISHED
1h ago
2026-11-13
RELEVANCE
9/ 10
AUTHOR
browser_use