OPEN LINK ↗
// 5h agoOPENSOURCE RELEASE
Budget3D drops compute-adaptive image-to-3D generation
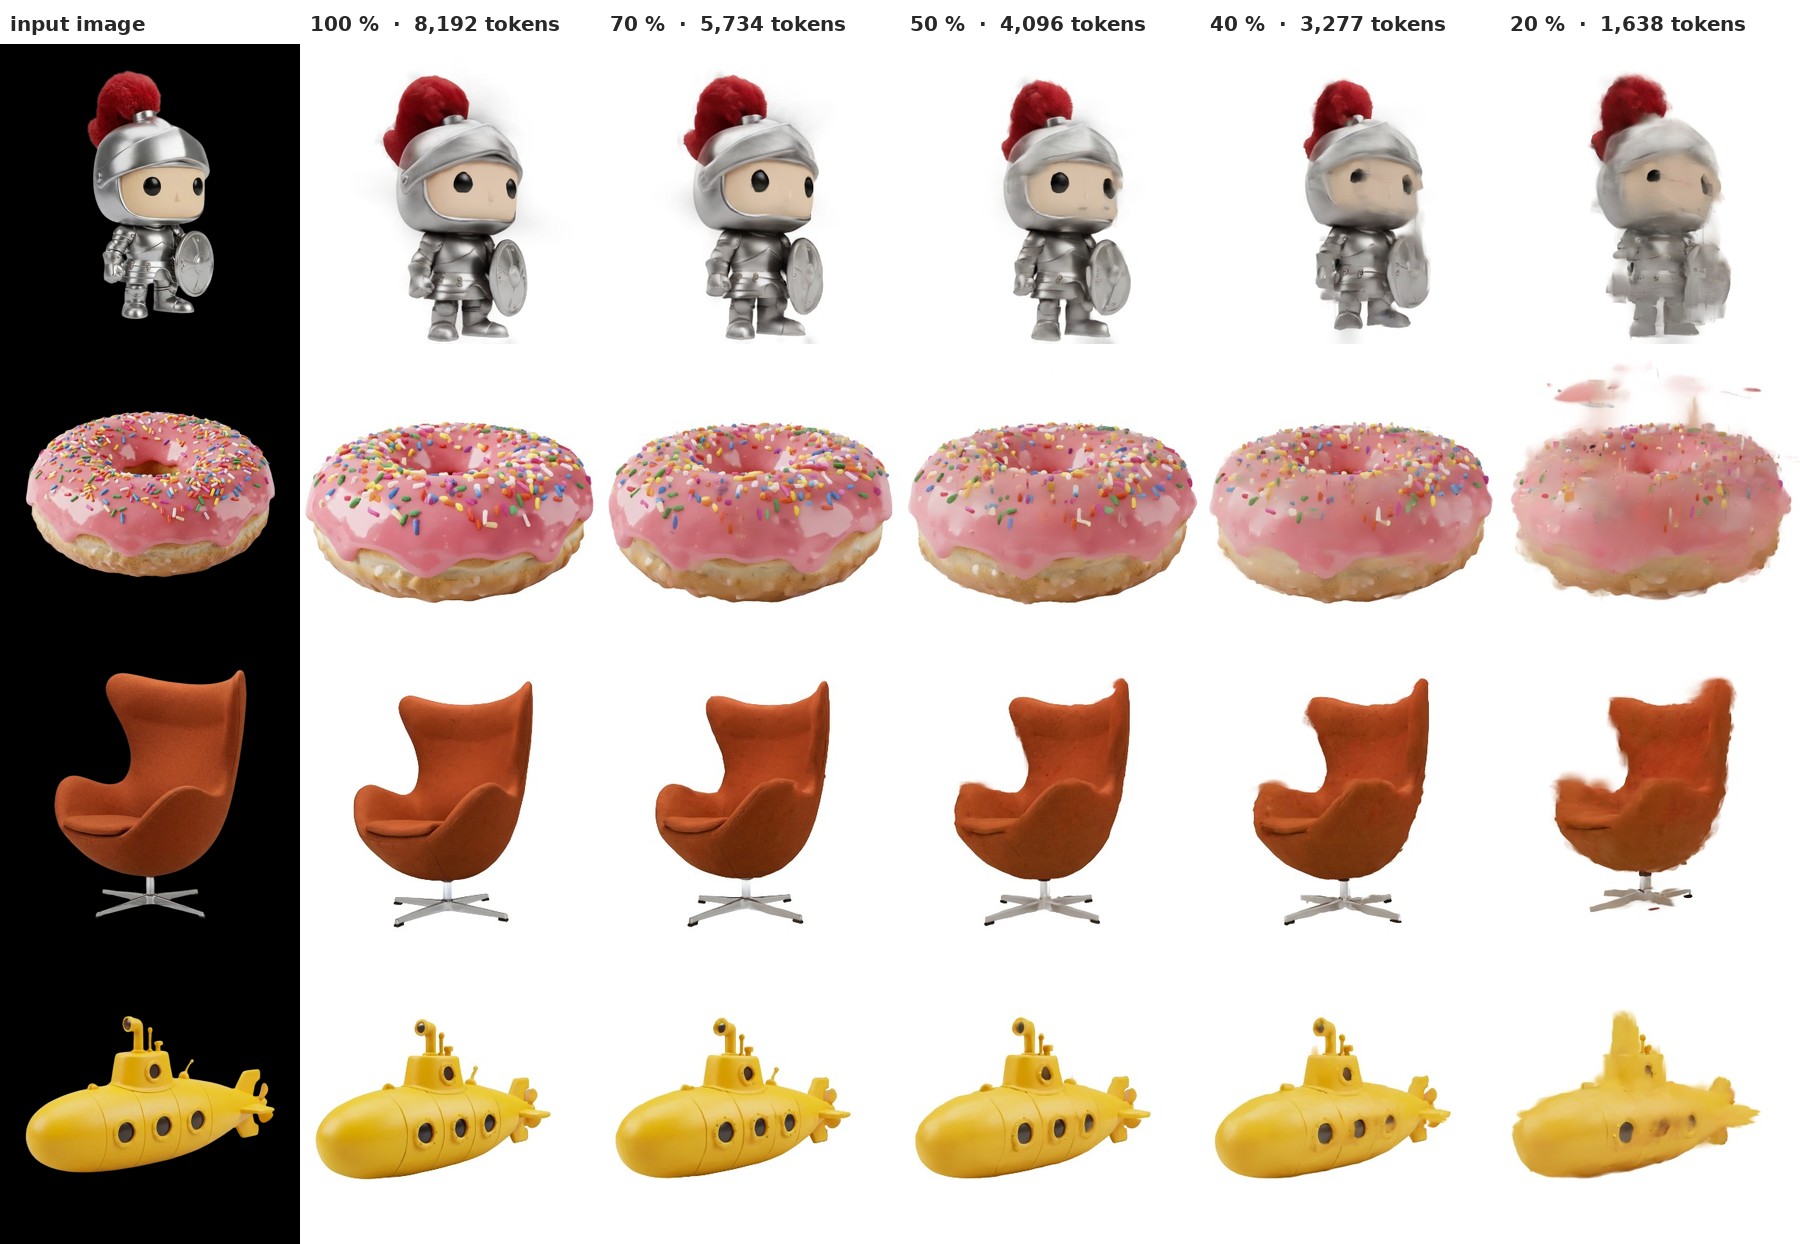
Budget3D extends compute-adaptive tokenization to 3D Gaussian splat generation, fine-tuning Idol and Idol-Turbo models to run at any user-defined token budget from 100% down to 40%. By merging empty space latents into coarser tokens at inference time, it delivers up to 2x speedups while reducing peak GPU memory.
// ANALYSIS
Most 3D generative diffusion models waste massive compute over-sampling empty space, making dynamic token allocation one of the most practical optimizations for real-time 3D synthesis.
- –Fine-tunes Sperid Labs' Idol and Idol-Turbo to dynamically scale inference from 8,192 tokens down to 3,277 tokens per object.
- –Cuts sampling latency by up to 2.14x (down to 0.25s per object on Idol-Turbo) and reduces peak VRAM by over 1.4 GB.
- –Adapts UIUC's BudgetPix approach to 3D Gaussian splat latents without requiring separate checkpoints for low-end versus high-end hardware.
- –Open-source weights under Apache 2.0 provide game developers and XR pipelines a viable drop-in mechanism for tiered latency budgets.
// TAGS
budget3d3d-genopen-weightsopen-sourceinferencemultimodal
DISCOVERED
5h ago
2026-11-15
PUBLISHED
5h ago
2026-11-15
RELEVANCE
8/ 10
AUTHOR
AI Search