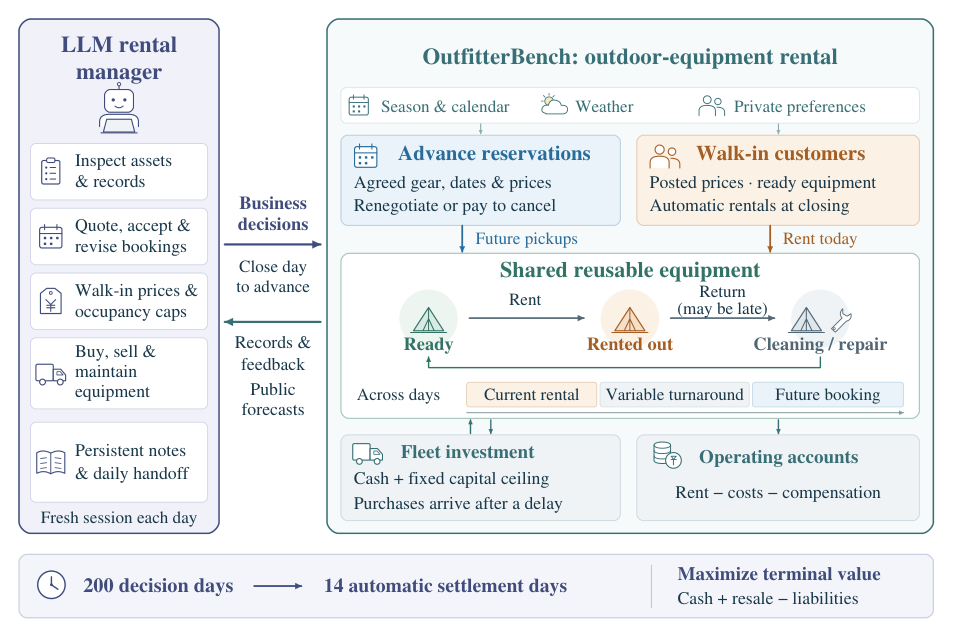
OutfitterBench benchmark reveals LLM agents struggle with long-horizon resource allocation tasks compared to rule-based baselines.
OutfitterBench is a new benchmark designed to evaluate the capability of Large Language Model (LLM) agents in handling complex, long-horizon tasks, specifically focusing on resource allocation and commitment coordination within a business simulation environment. The simulation places agents in the role of managing an outdoor-equipment rental business over a 200-day period, requiring them to manage a product catalog, capital constraints, and reservation requests against uncertain demand. Initial findings highlight a significant gap in performance, with LLM agents failing to outperform simple rule-based strategies.
This research underscores a critical bottleneck in the current state of LLM agents: long-term planning and adherence to constraints over extended horizons. While LLMs excel at short-term reasoning and pattern matching, their performance in dynamic, multi-step environments that require state maintenance and commitment tracking remains limited.
* Demonstrates that LLMs often struggle to dynamically reallocate resources in response to shifting demands.
* Shows a 76% performance improvement of "Fixed Rules" over high-performance models like Opus 5.5 in generated business value.
* Identifies that current LLM agents lack the robust capability to maintain consistency over 200-day simulated horizons.
DISCOVERED
3h ago
2026-11-17
PUBLISHED
3h ago
2026-11-17
RELEVANCE
AUTHOR
Discover AI