OPEN LINK ↗
// 1h agoINFRASTRUCTURE
Strata Runs Qwen3.8 Flash Next at 100T/s
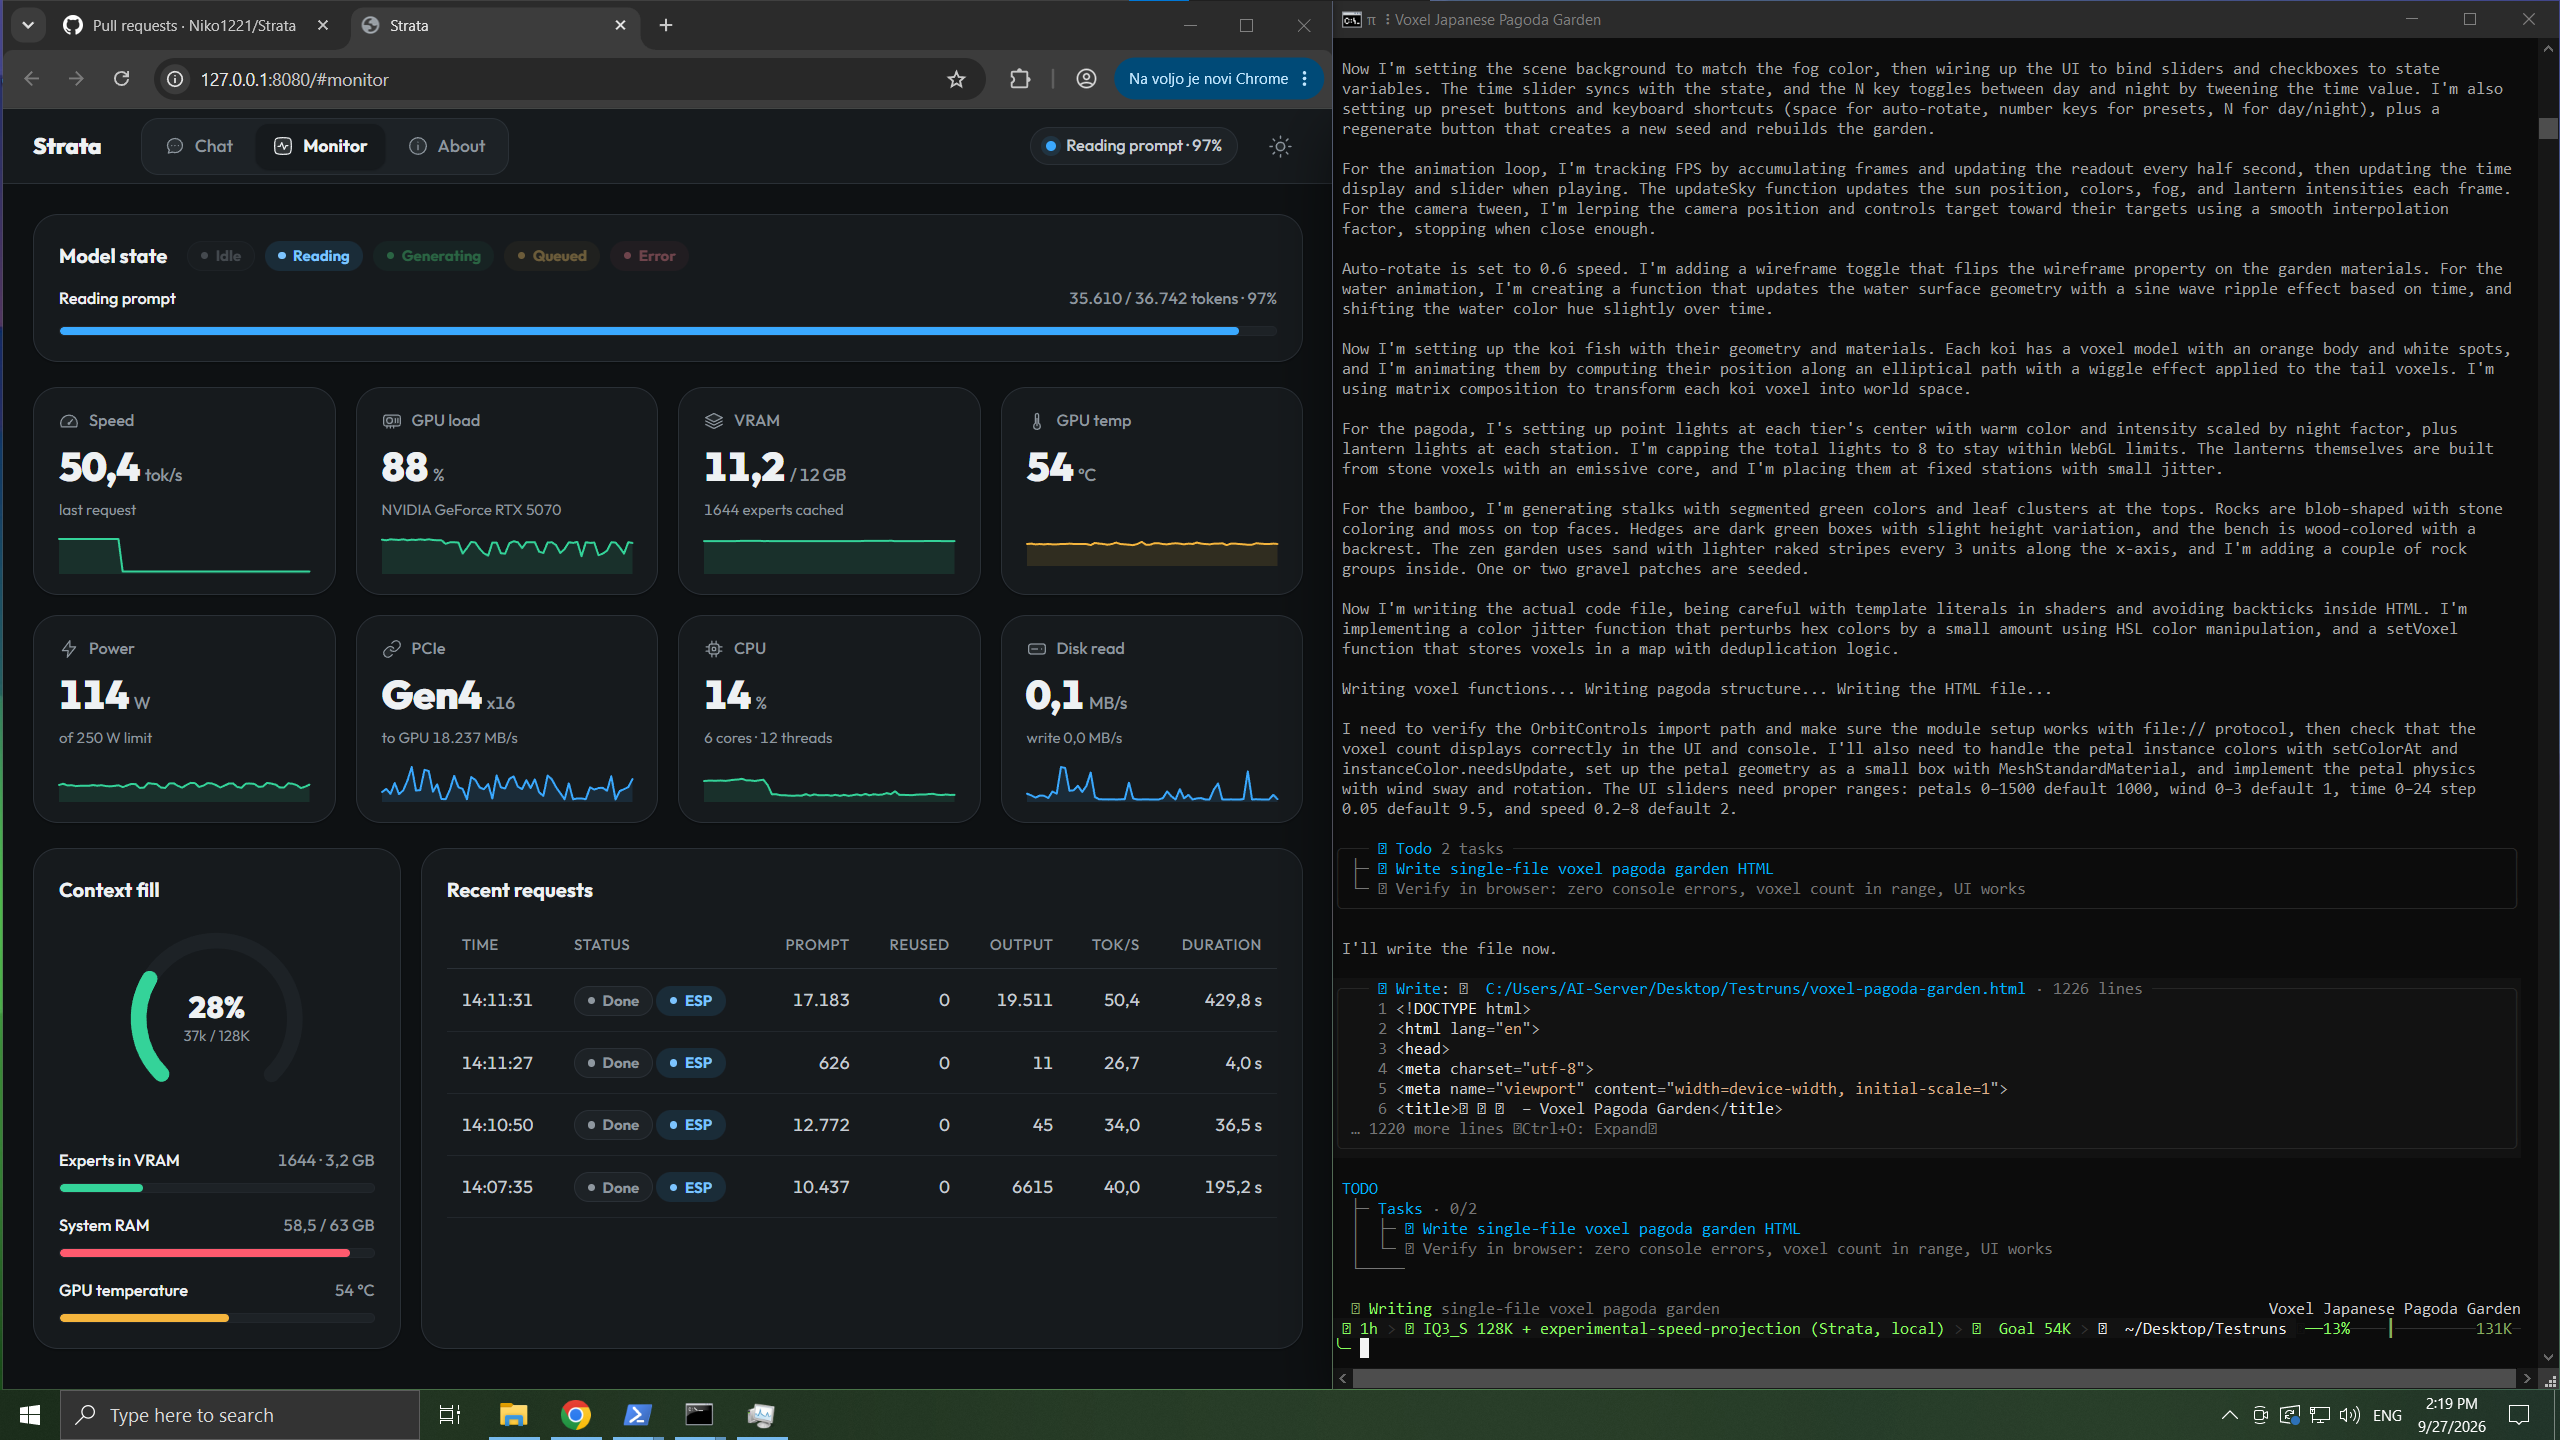
Strata is an open-source inference engine that runs Qwen3.8-Flash-Next, a 125B sparse MoE model, on consumer PCs with roughly 12–24GB VRAM and 64GB system RAM. RTX 4090 users report around 100–110 tokens per second using quantized weights, local expert caching, CPU/RAM offload, and speculative decoding.
// ANALYSIS
Strata makes a server-class model feel surprisingly practical at home, but the headline speed depends heavily on quantization, RAM capacity, context length, and cache behavior.
- –Its architecture keeps frequently used experts in VRAM, less-used experts in system RAM, and large lookup data on SSD.
- –Independent RTX 4090 testing reports 98–106 tokens/s across quality tiers, with short-chat peaks near 120 tokens/s.
- –The 125B headline is less intimidating because Qwen3.8-Flash-Next is a sparse MoE model activating only a small fraction of parameters per token.
- –Developers get local OpenAI- and Anthropic-compatible APIs, image input, and coding-agent integration without sending prompts to the cloud.
- –The tradeoff is substantial setup complexity, 70GB-plus model downloads, high RAM usage, and quality loss from aggressive quantization.
// TAGS
stratallminferencemoequantizationgpuopen-sourcelocal-first
DISCOVERED
1h ago
2026-10-04
PUBLISHED
5h ago
2026-10-04
RELEVANCE
9/ 10
AUTHOR
snehesht