OPEN LINK ↗
// 32m agoPRODUCT UPDATE
T3 Code Fork Makes Local Models Default
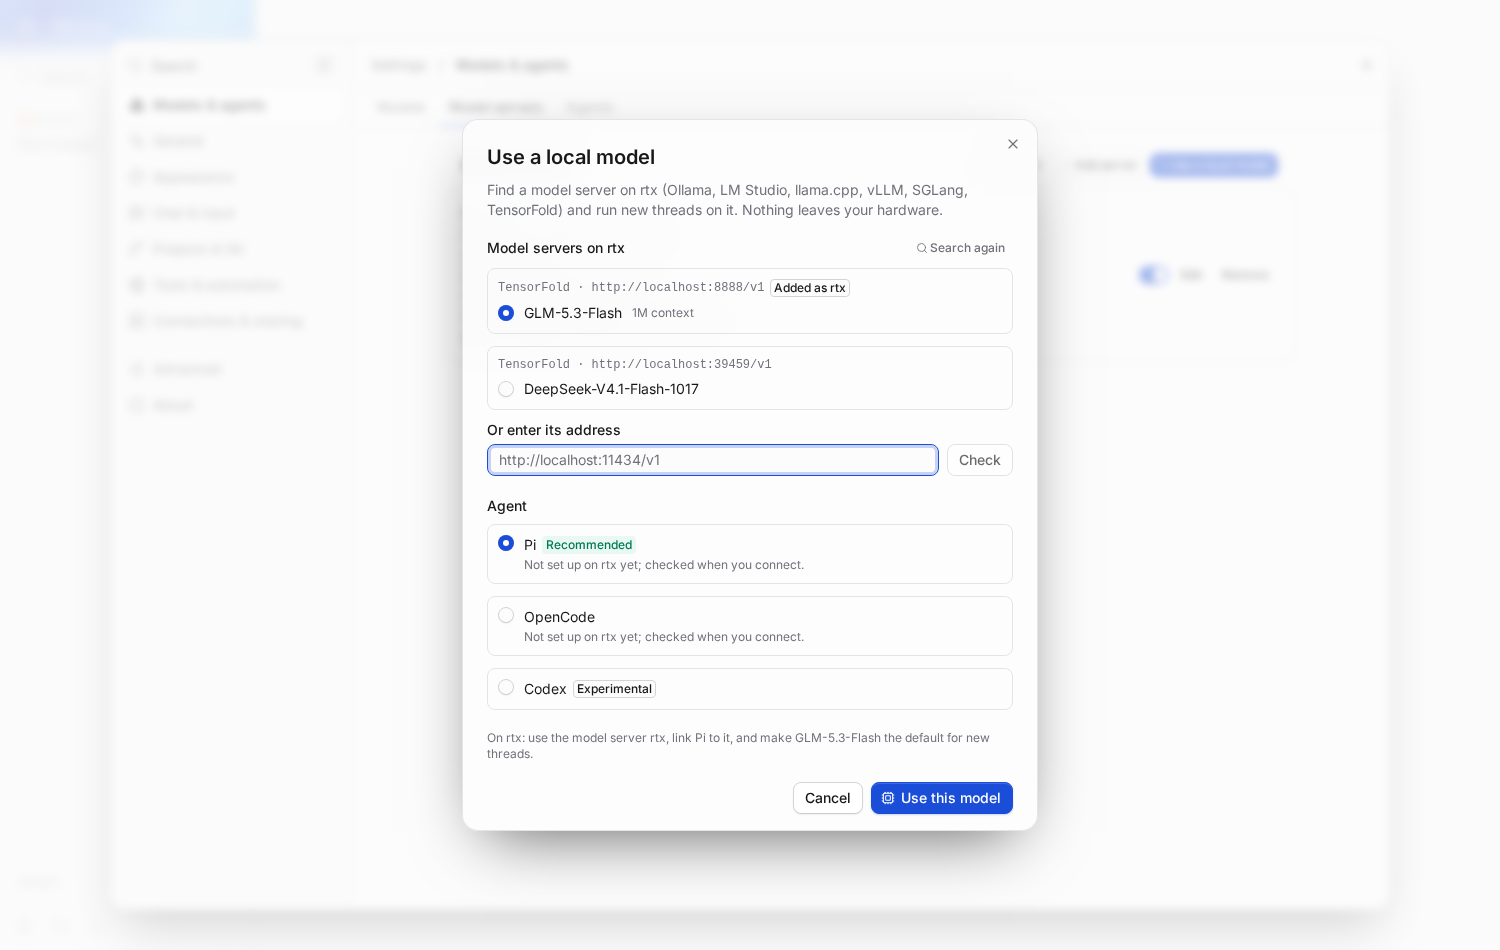
MiaAI-Lab’s T3 Code fork adds a Settings → Inference page for connecting Ollama, LM Studio, llama.cpp, vLLM, SGLang, and other OpenAI-compatible servers. Local models become the default, with cloud providers retained as fallback options.
// ANALYSIS
This is a meaningful shift from AI coding subscriptions toward self-hosted inference, turning T3 Code into a local-first orchestration layer.
- –Registers inference servers and links them directly to Pi, OpenCode, or Codex without manual provider configuration
- –Queues requests per GPU server to prevent parallel coding threads from overwhelming local hardware
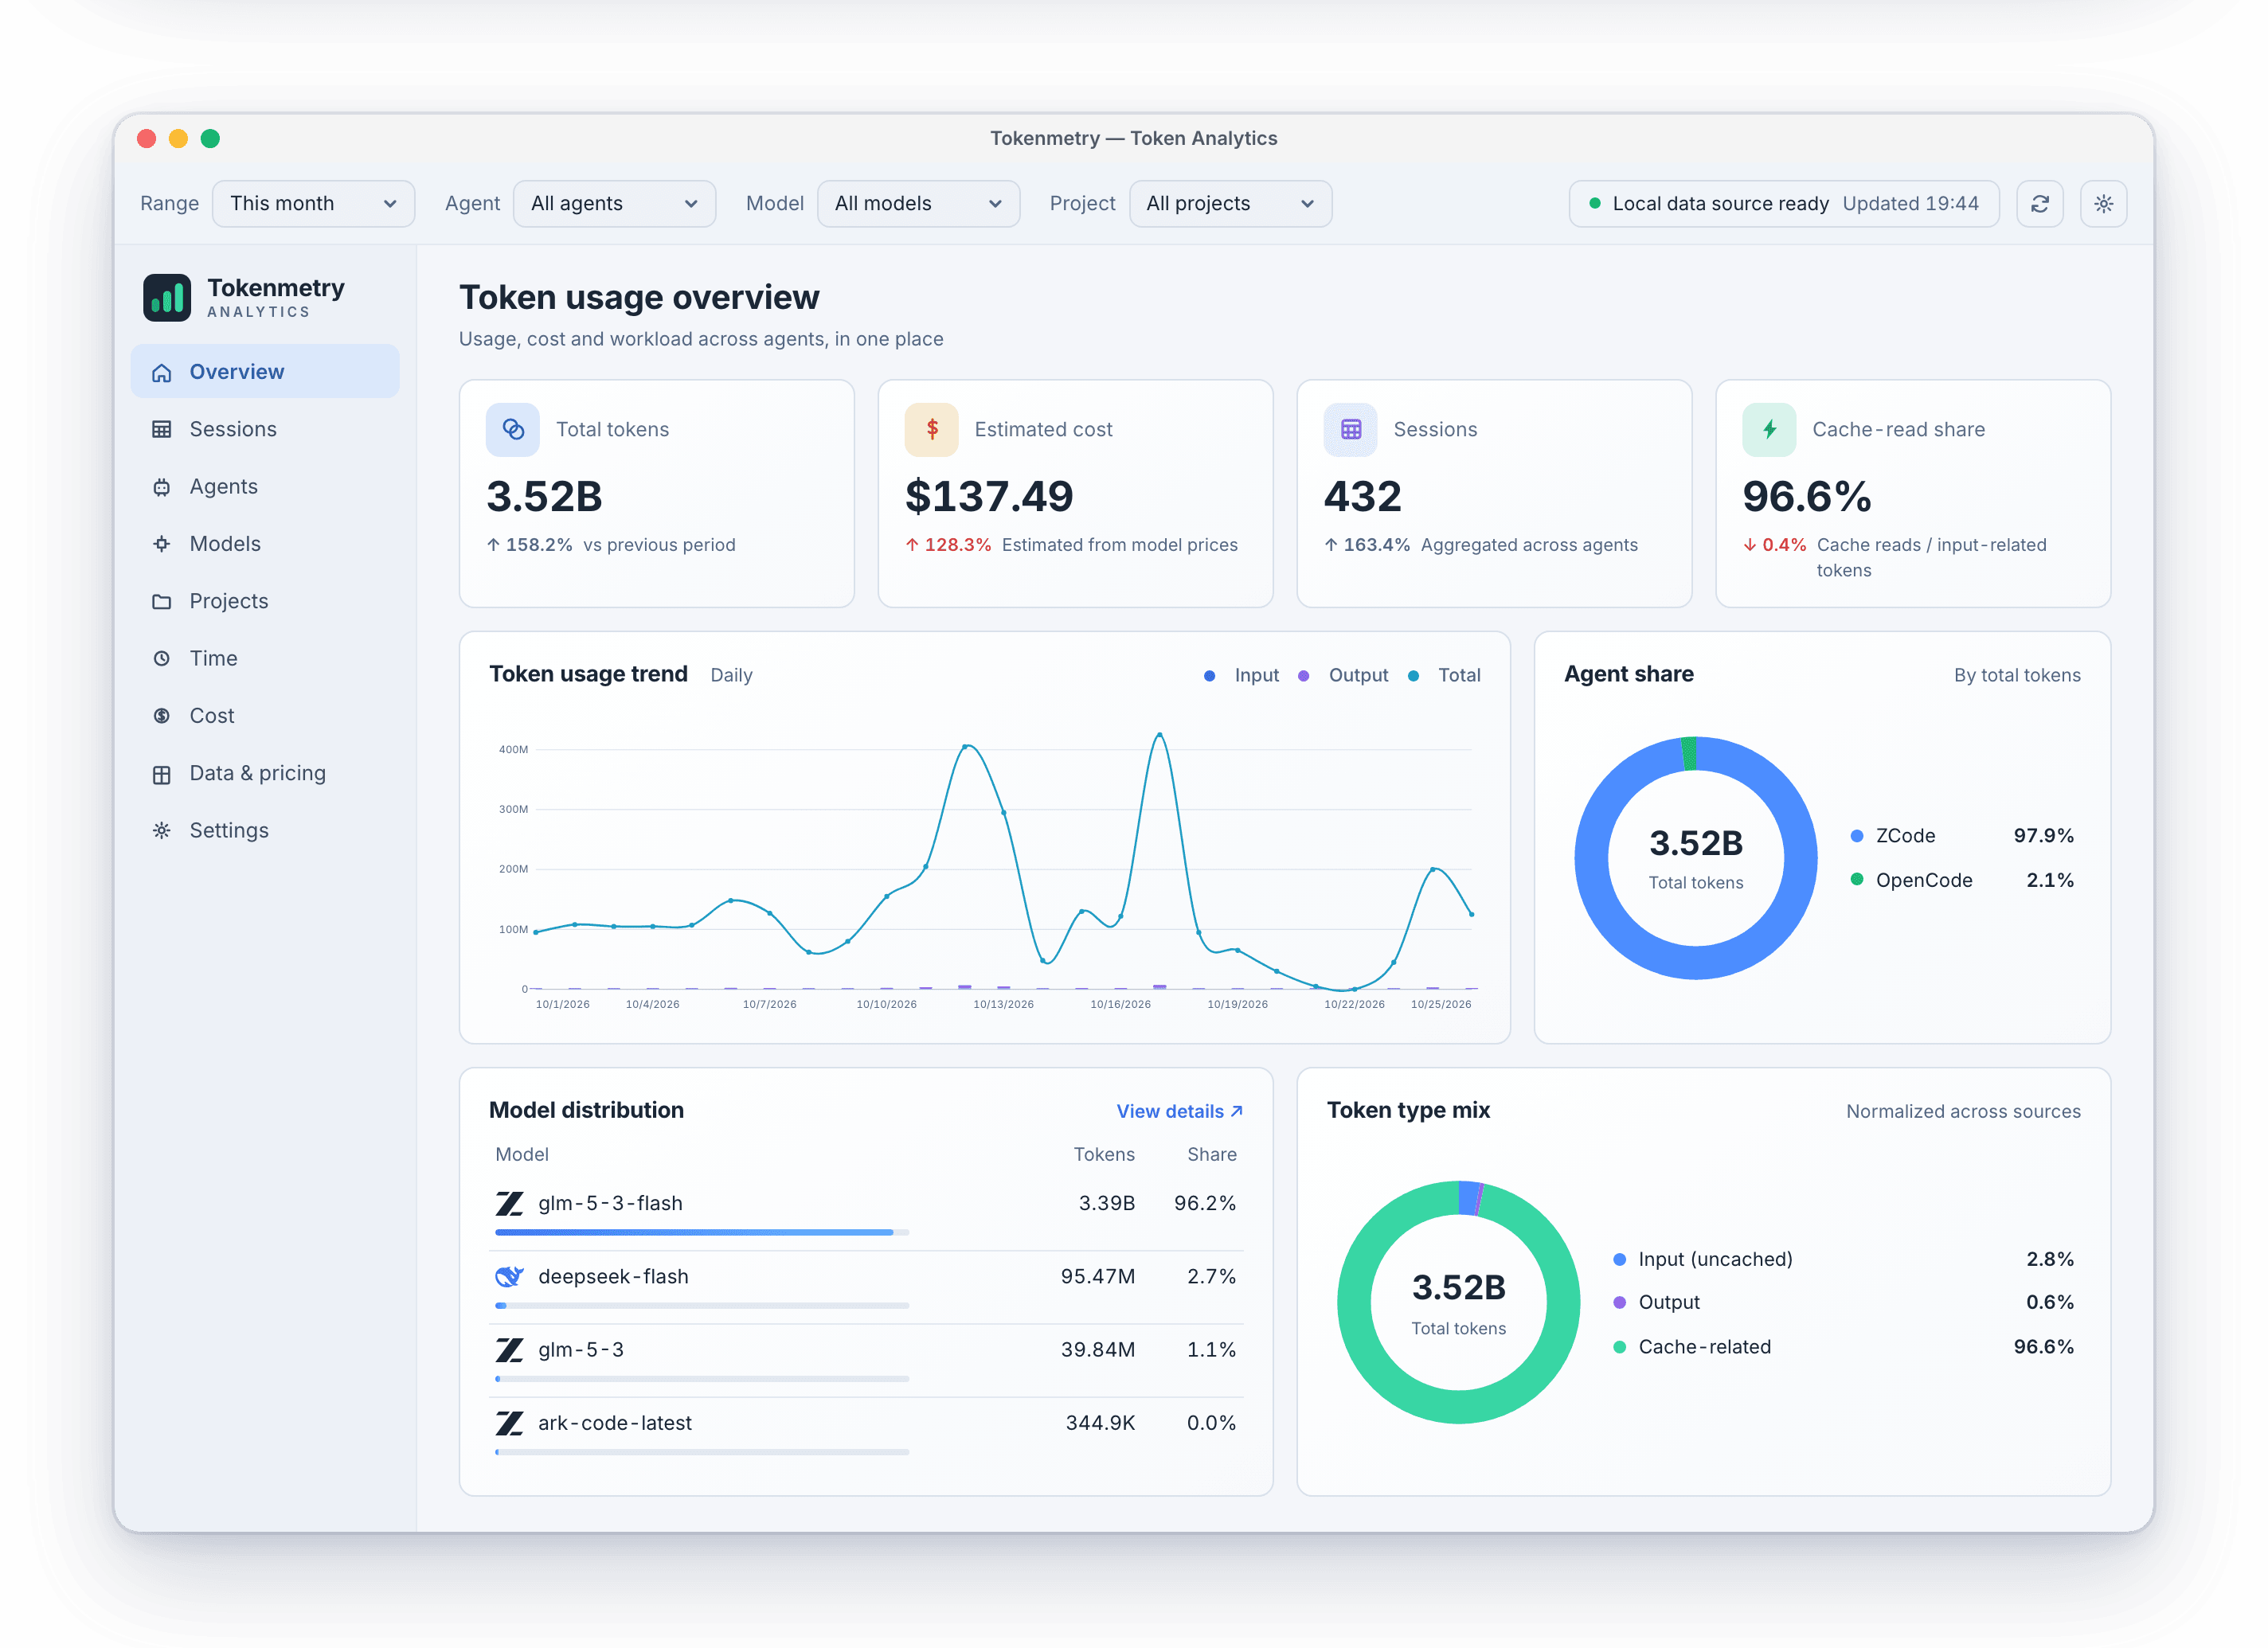
- –Adds health monitoring, fallback routing, token metrics, cache statistics, and latency tracking
- –Keeps titles, commits, pull-request text, and other background generation on local models
- –The main caveat is distribution: this is an independent fork, not an upstream T3 Code release
// TAGS
t3-codeai-codingcoding-agentinferenceself-hostedlocal-firstopen-sourcedevtool
DISCOVERED
32m ago
2026-11-08
PUBLISHED
1h ago
2026-11-08
RELEVANCE
9/ 10
AUTHOR
0x0SojalSec