OPEN LINK ↗
// 1h agoMODEL RELEASE
Tencent Releases WeVisOne-VL in 2B, 4B
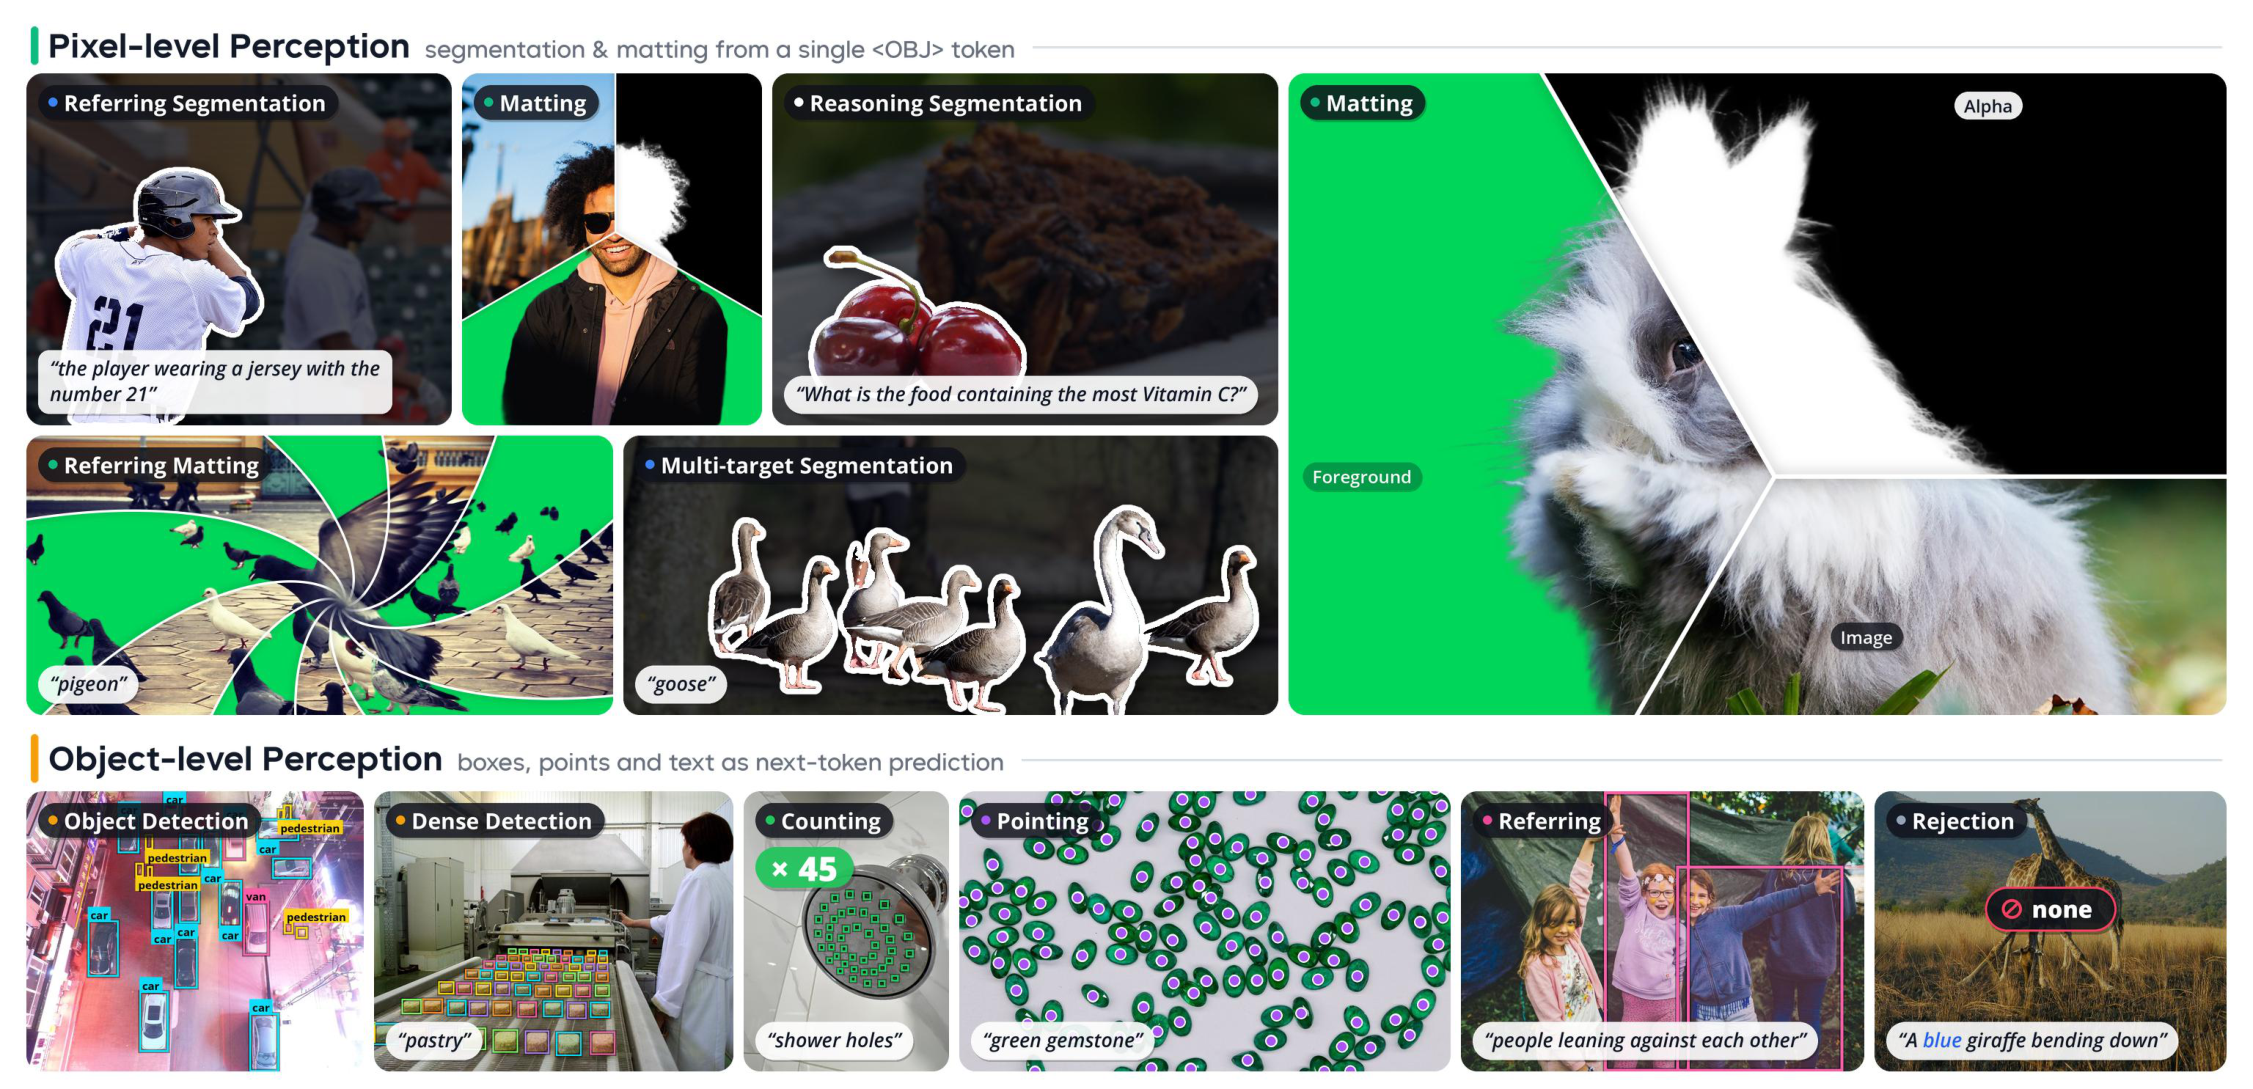
Tencent’s WeChat Vision team released WeVisOne-VL, an open-weight vision-language model combining detection, counting, pointing, OCR, segmentation, and alpha matting. Its 2B and 4B variants support local Transformers or vLLM inference under Apache 2.0.
// ANALYSIS
WeVisOne-VL’s strongest idea is consolidation: one compact model handles tasks developers typically split across several specialized vision systems.
- –A lightweight 9.6M-parameter pixel decoder produces masks and alpha mattes without requiring SAM or an external segmentation backbone. [Official method overview](https://tencent.github.io/WeVisOne-VL/)
- –Structured coordinate tokens unify boxes, points, masks, OCR grounding, and absent-target rejection in one output format.
- –Tencent reports strong 4B results, including 55.3 LVIS F1, 96.4% rejection on WeRef-Bench, and 71.2 ReasonSeg gIoU. [Benchmark results](https://github.com/Tencent/WeVisOne-VL)
- –Apache 2.0 licensing, downloadable weights, evaluation code, and local inference make it practical for privacy-sensitive visual search, document processing, and image-editing pipelines.
- –The main caveat is deployment cost: “2B” and “4B” still require serious GPU resources for high-resolution pixel tasks, so specialists may remain cheaper for narrow workloads.
// TAGS
wevisone-vlmultimodalvisionocropen-weightsopen-sourceinference
DISCOVERED
1h ago
2026-10-25
PUBLISHED
1h ago
2026-10-25
RELEVANCE
9/ 10
AUTHOR
AI Search