OPEN LINK ↗
// 1h agoMODEL RELEASE
MiniCPM-V 4.7 brings 35B MoE on-device
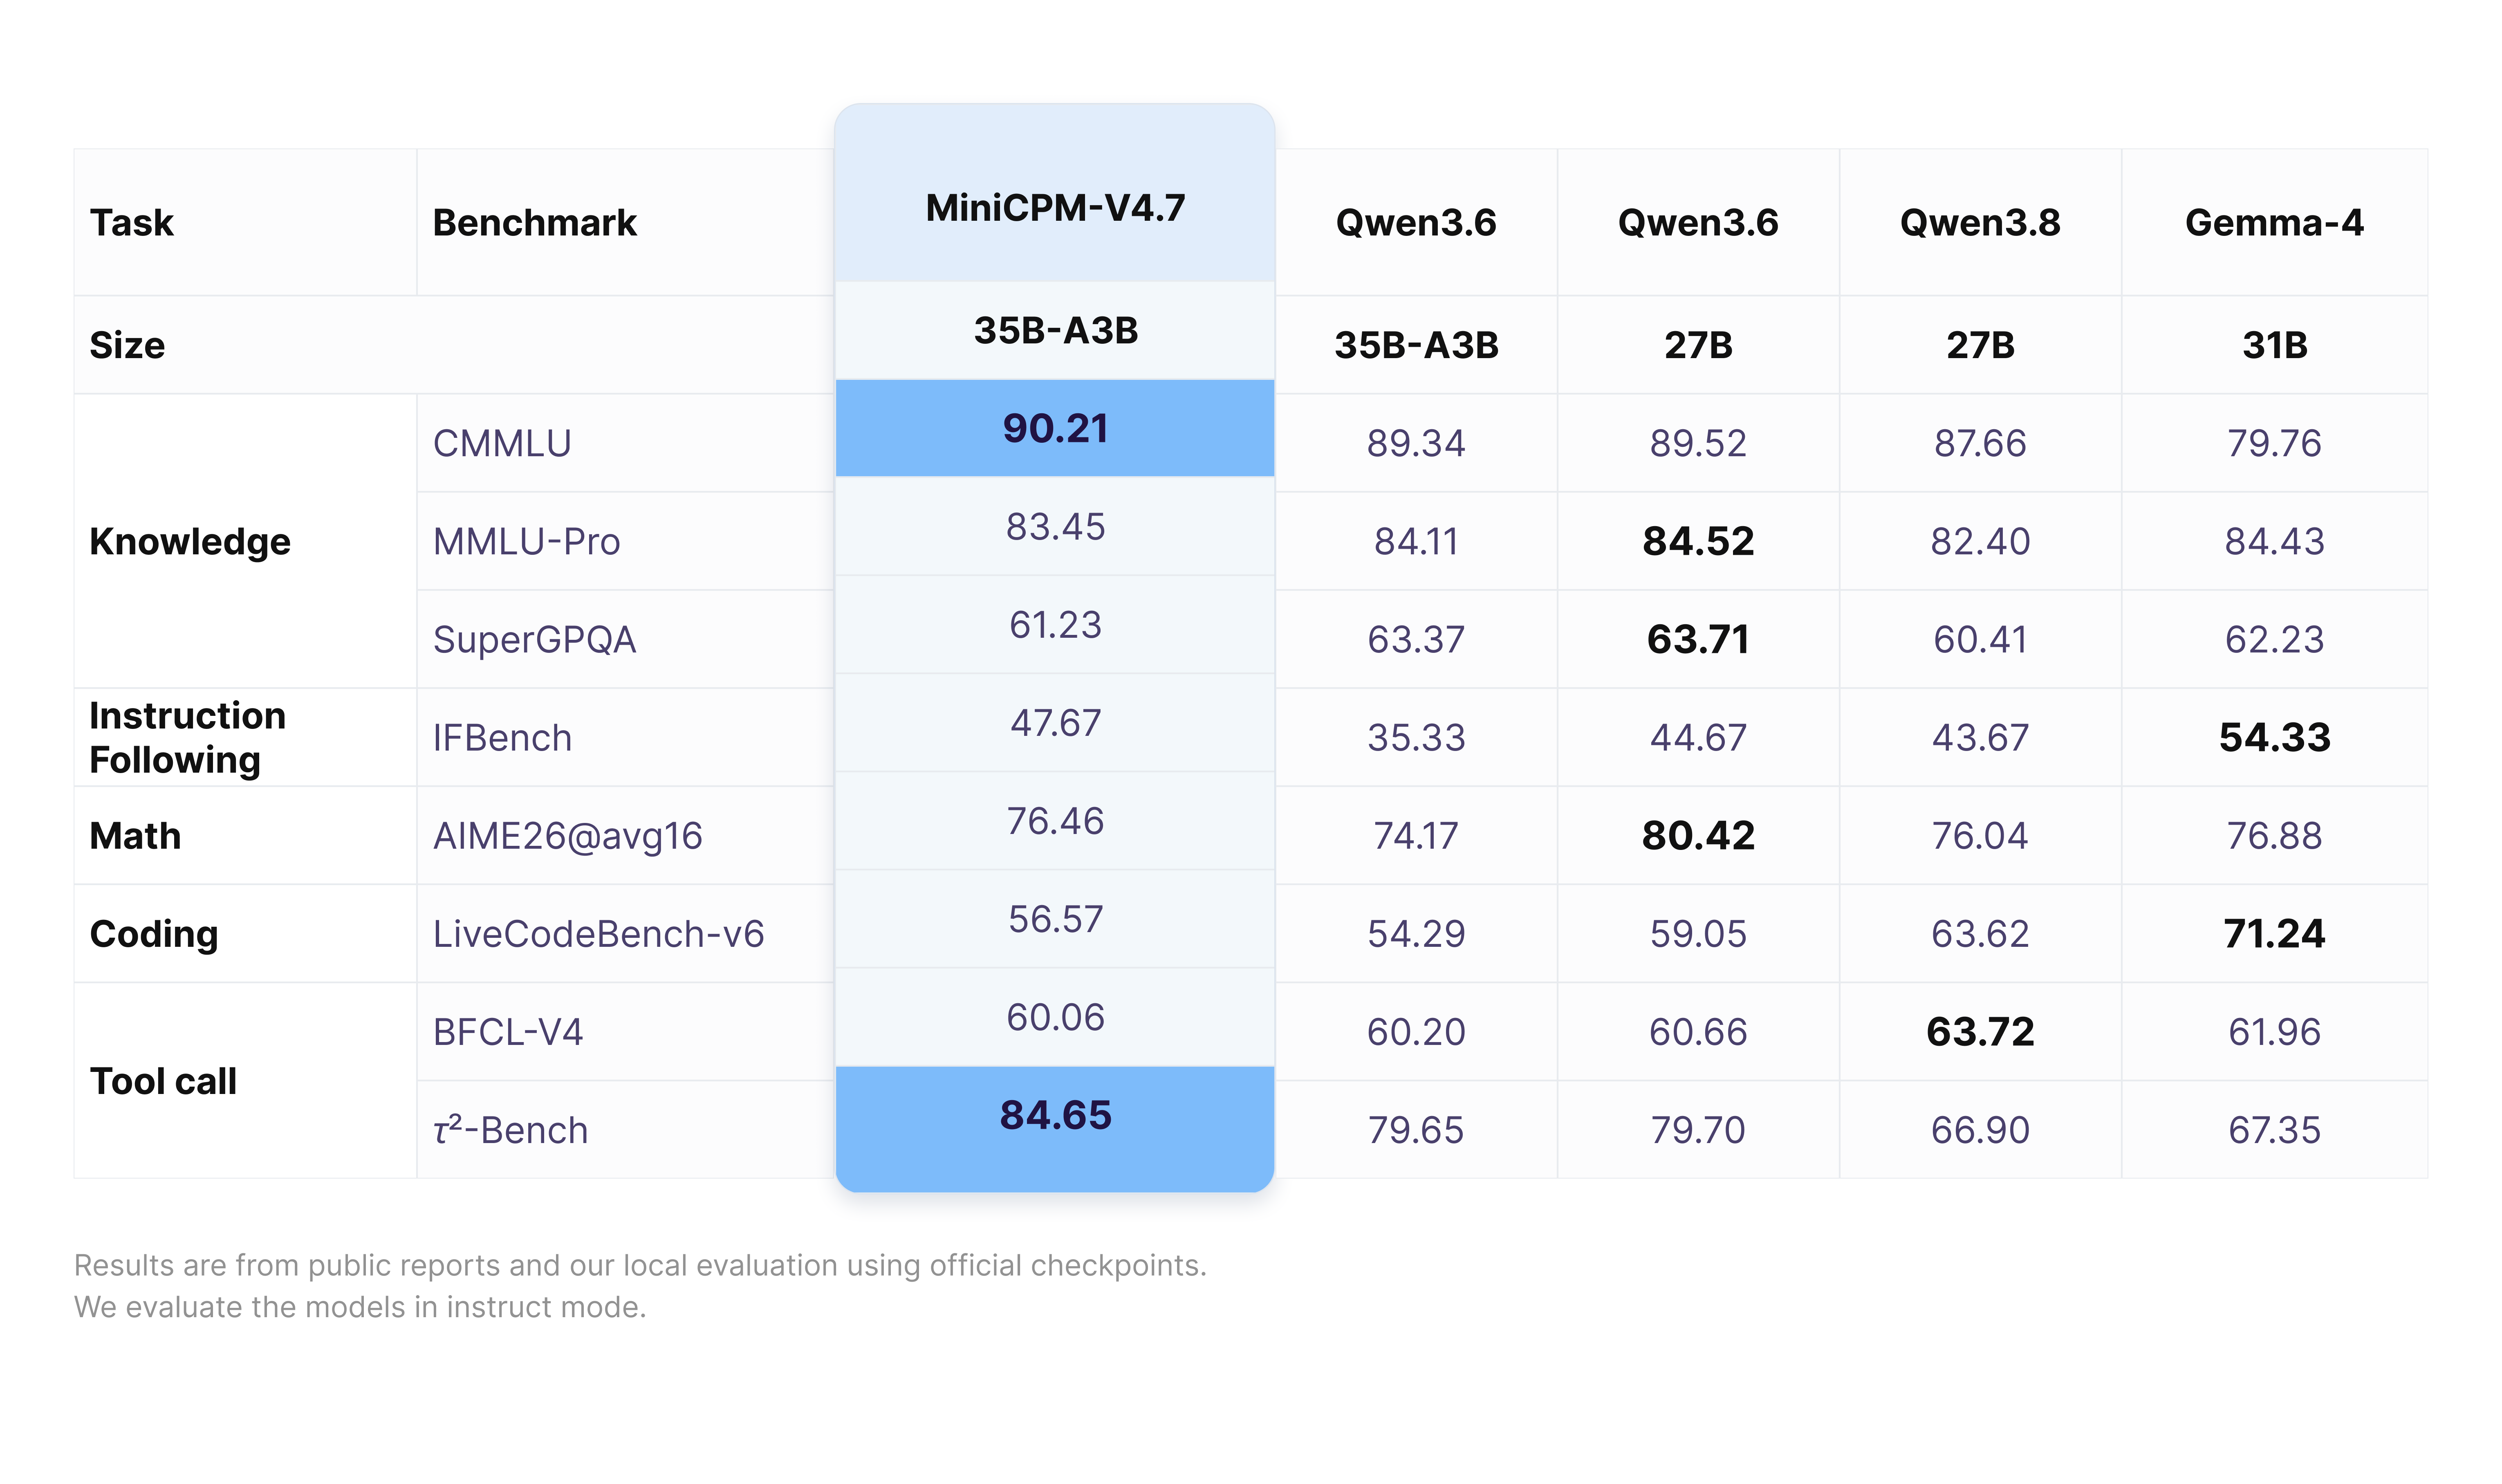
OpenBMB’s open-source multimodal release pairs a dense 1B variant with a sparse 35B-A3B MoE designed for local inference. The larger model reportedly reaches 13+ tokens/s on an iPhone 17 Pro Max, while the 1B model claims stronger performance and efficiency than Qwen3.5 0.8B.
// ANALYSIS
MiniCPM-V 4.7’s real breakthrough is systems engineering: aggressive visual compression, expert scheduling, quantization, and speculative decoding make serious multimodal models plausible on phones. The performance claims are compelling but remain vendor-reported and need independent reproduction.
- –The 35B-A3B model activates only a fraction of its MoE experts per token, while Lookahead Expert Scheduling reduces memory-loading stalls.
- –The 1B variant targets practical offline vision, OCR, video, and image understanding within a roughly 3 GB checkpoint.
- –Apache-2.0 licensing plus support for llama.cpp, Ollama, vLLM, SGLang, GGUF, AWQ, GPTQ, and FP8 gives developers a usable deployment path.
- –The 13+ tokens/s iPhone result and benchmark advantages lack machine-readable scores and independent validation.
- –If reproduced, this could shift multimodal applications toward private, offline, edge-first deployments.
// TAGS
minicpm-v-4-7multimodalvisionsmall-llmopen-weightsmoeedge-aiinference
DISCOVERED
1h ago
2026-10-13
PUBLISHED
1h ago
2026-10-13
RELEVANCE
9/ 10
AUTHOR
0x0SojalSec