OPEN LINK ↗
// 1h agoOPENSOURCE RELEASE
ModelSphere Opens Heterogeneous LLM Serving Stack
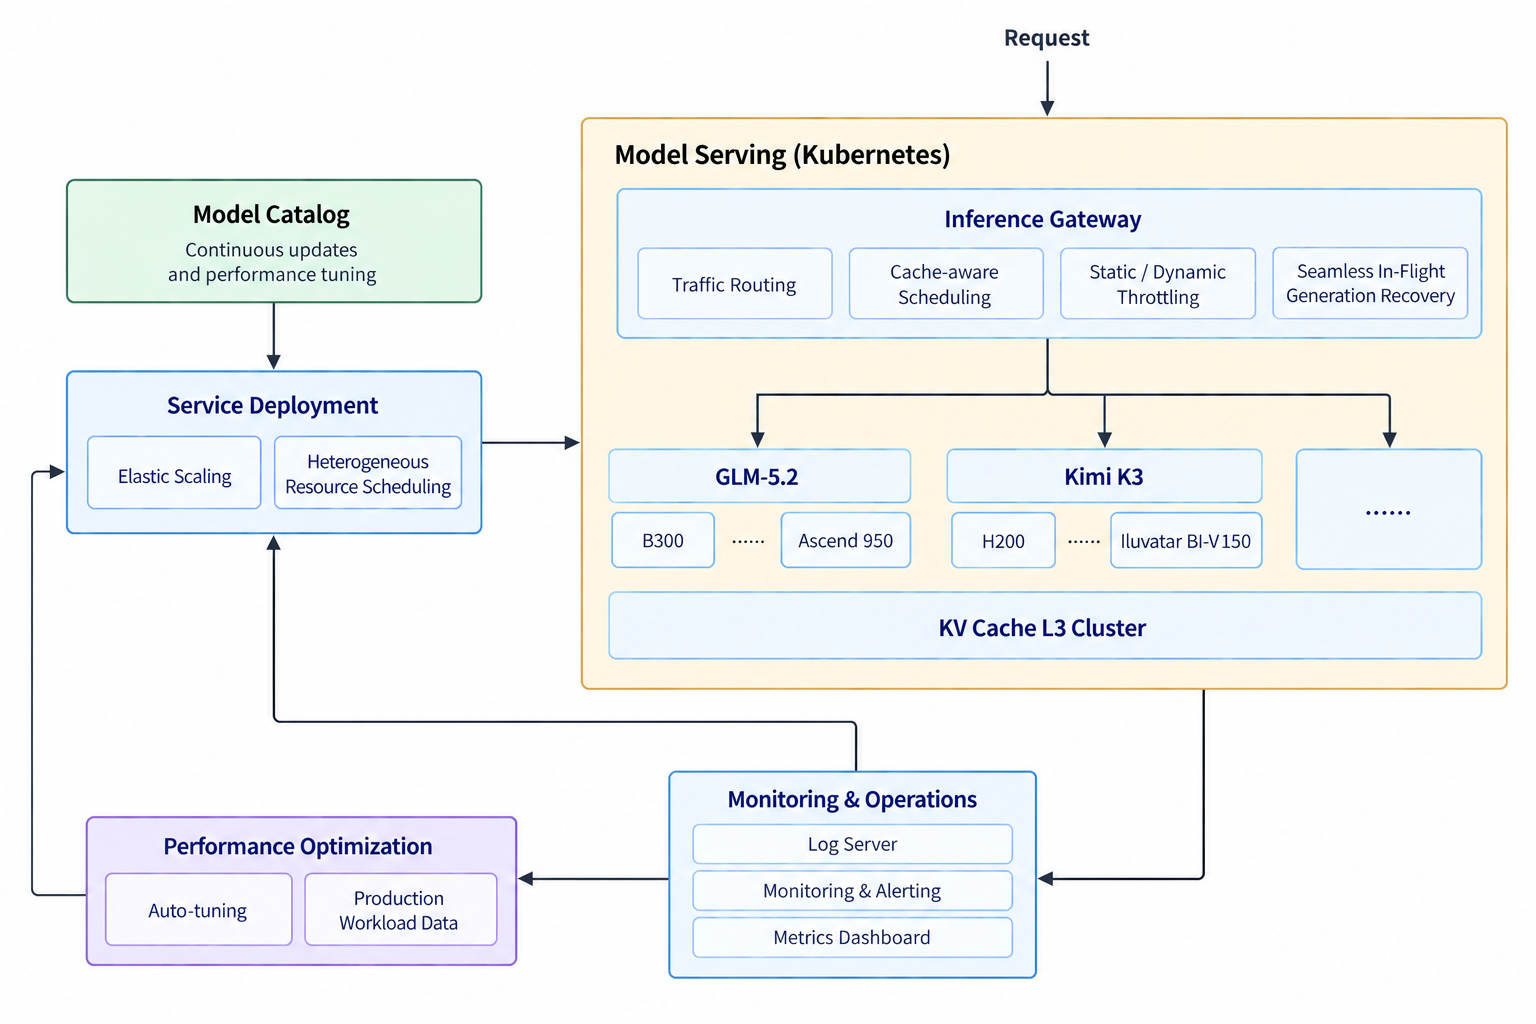
4Paradigm and RiseUnion open-sourced ModelSphere under Apache 2.0, combining cluster routing, shared L3 KV caching, autoscaling, failure recovery, and workload-driven AutoTune above vLLM and SGLang. The project targets production LLM serving across mixed accelerator fleets, including Huawei Ascend and Iluvatar.
// ANALYSIS
ModelSphere’s strongest idea is operational abstraction: it addresses the messy cluster, cache, and hardware layer that single-node inference engines leave to platform teams.
- –Complements vLLM and SGLang with fleet-level routing, autoscaling, prefill/decode disaggregation, and shared KV-cache management.
- –Heterogeneous accelerator support could matter significantly for organizations operating NVIDIA GPUs alongside domestic Chinese hardware.
- –In-flight generation recovery and quality-aware throttling target real production pain points, especially for latency-sensitive services.
- –AutoTune is still marked preview, while performance claims require independent benchmarks and broader community validation.
- –Kubernetes, Helm, and Helmfile prerequisites make this a serious infrastructure deployment rather than a lightweight serving library.
// TAGS
modelsphereopen-sourceinferencellmgpuself-hostedmlops
DISCOVERED
1h ago
2026-10-17
PUBLISHED
1h ago
2026-10-17
RELEVANCE
9/ 10
AUTHOR
thePandaily