OPEN LINK ↗
// 1h agoRESEARCH PAPER
Memorilla Shrinks LLM Memory to 16 Tokens
Memorilla compresses entire document collections into 16 query-dependent latent tokens that frozen LLMs can consume. Its paper reports 84.33% FactKG accuracy—beating full-context inference—while using 108× fewer source tokens.
// ANALYSIS
Memorilla makes a compelling case that learned, query-conditioned compression can outperform simply stuffing more context into an LLM.
- –Precomputed document embeddings keep storage separate from the frozen language model, enabling scalable external memory.
- –It outperforms Mem0, MemoRAG, and other baselines on five of eight benchmarks.
- –The fixed token budget could make long-term agent memory cheaper and more predictable.
- –Results deserve scrutiny because the memory module receives task-specific training while several baselines are evaluated off the shelf.
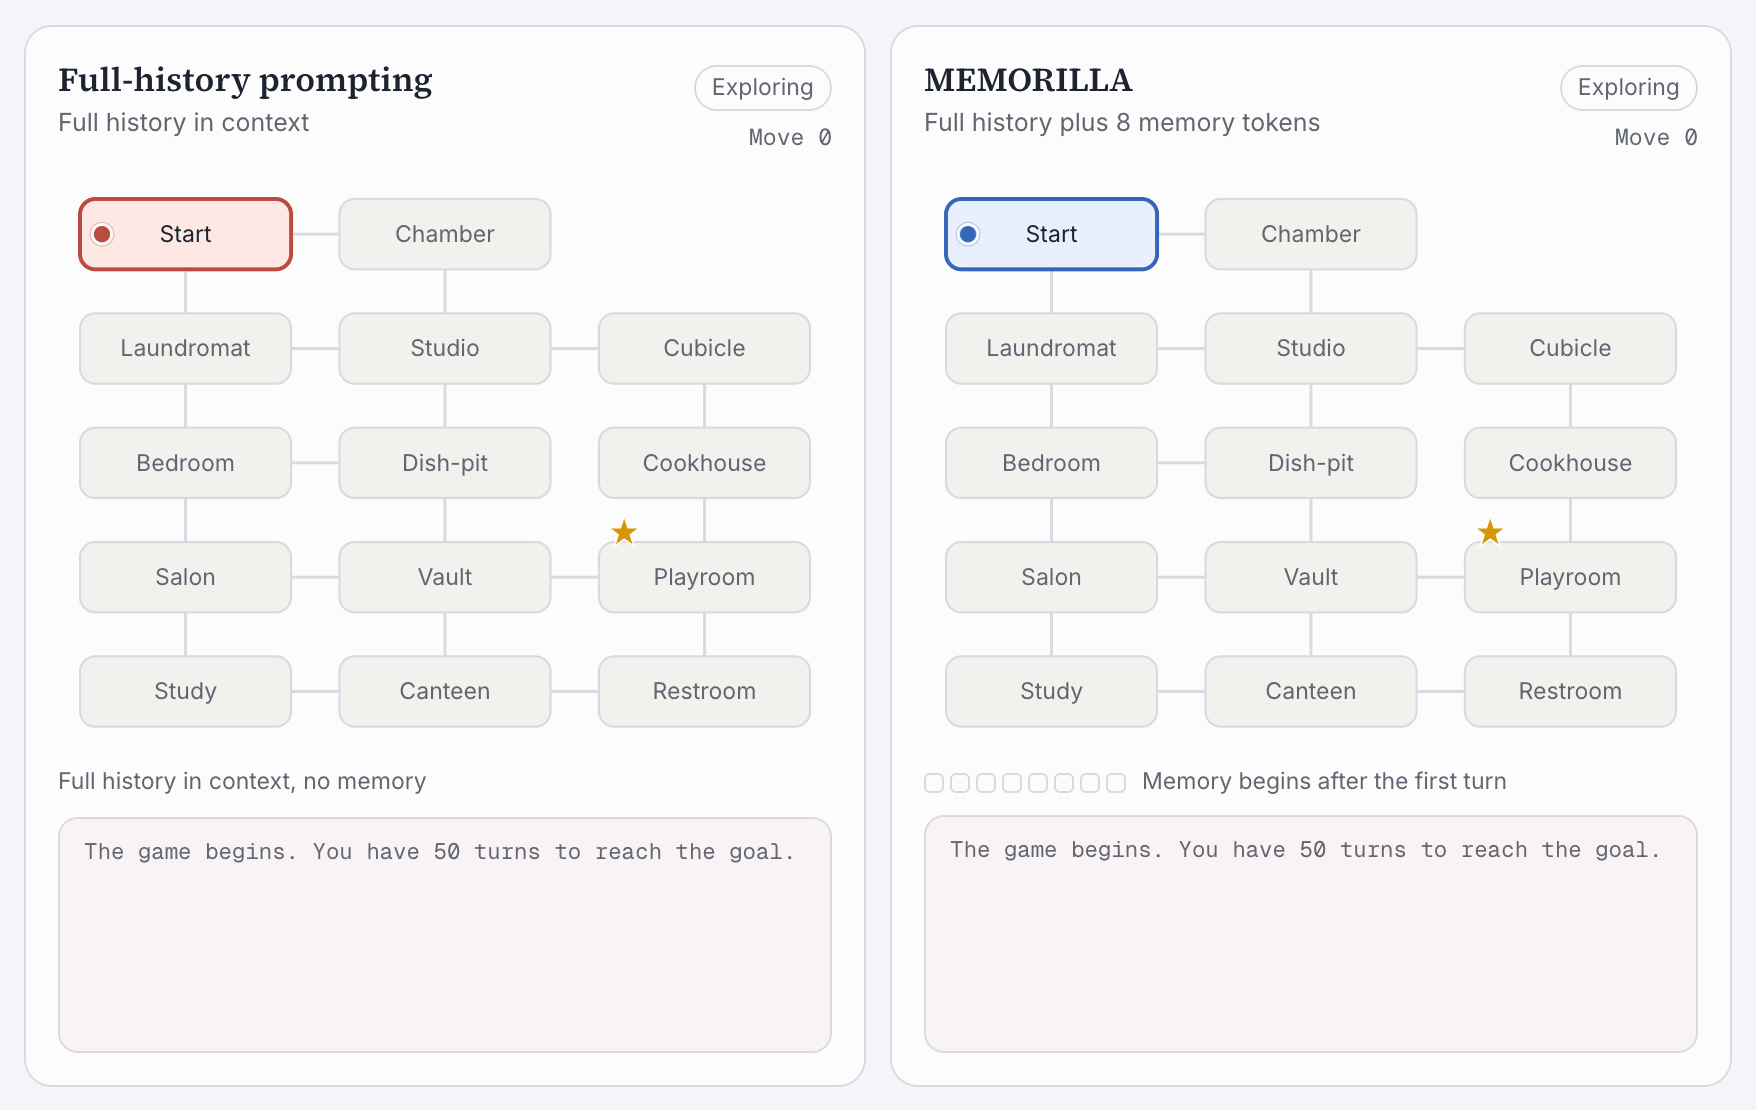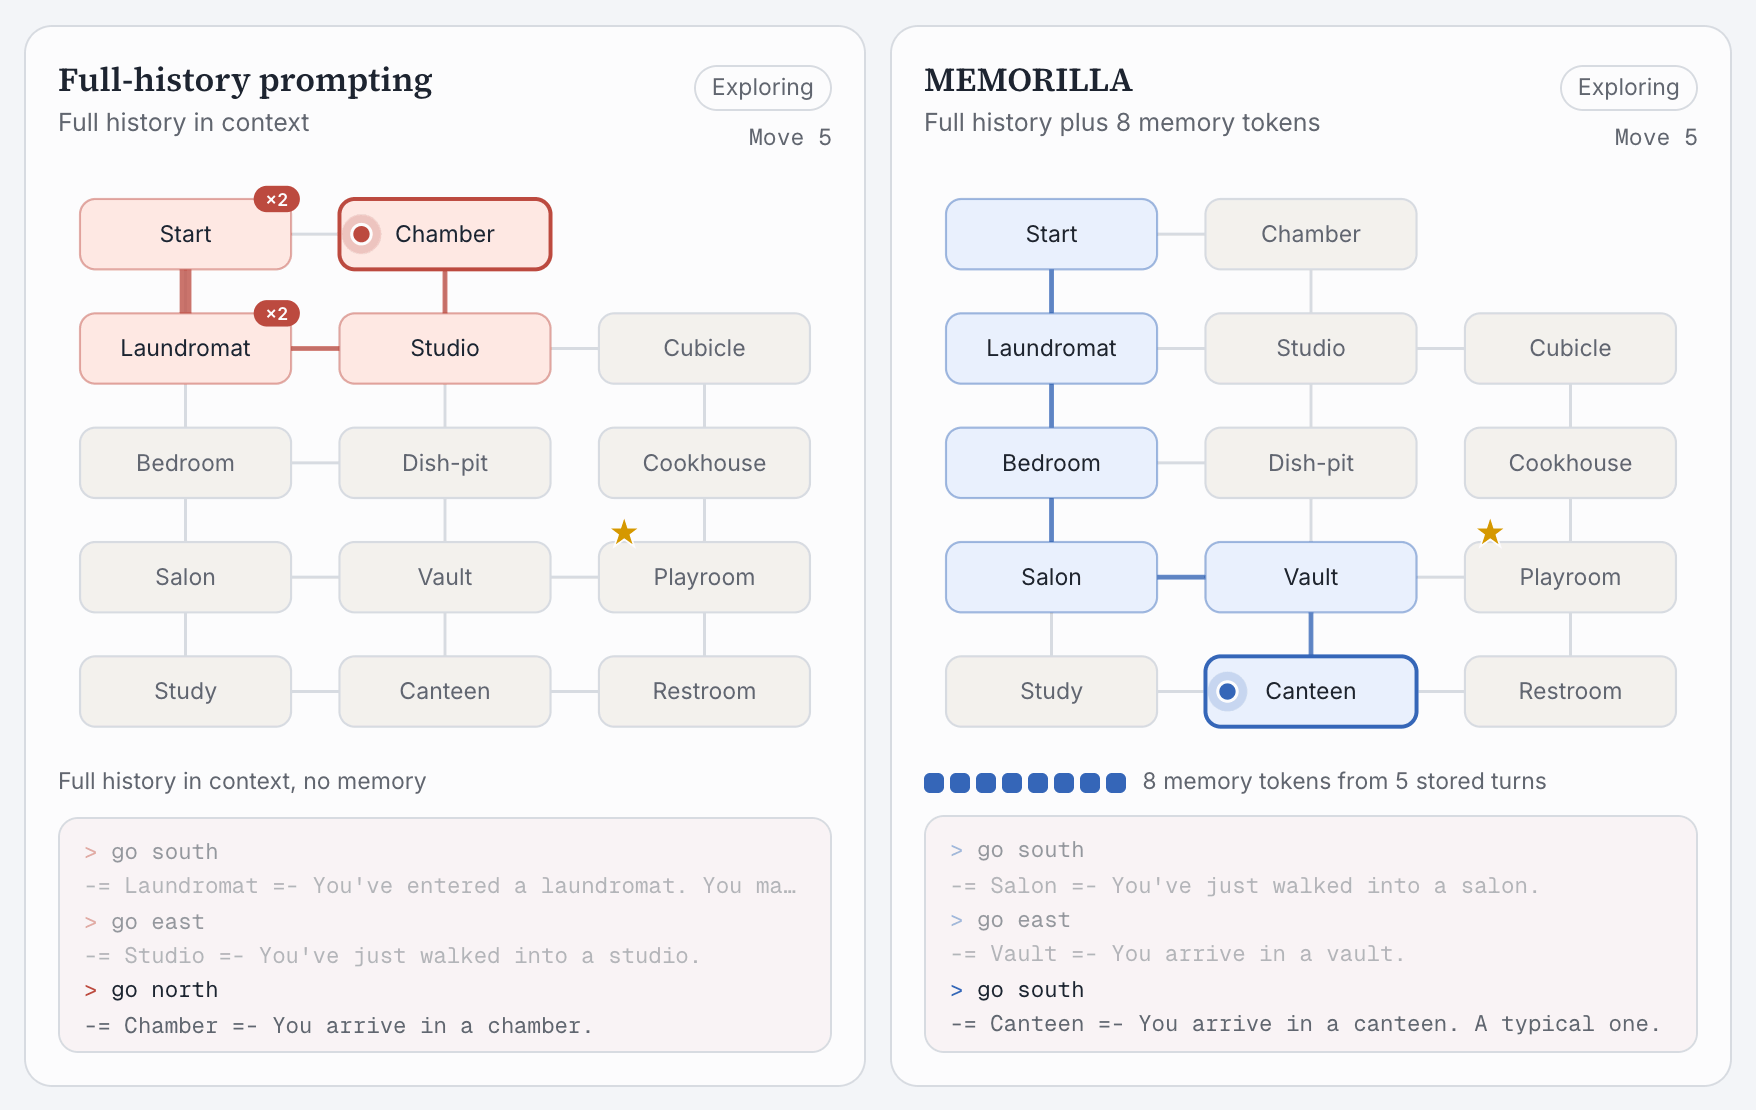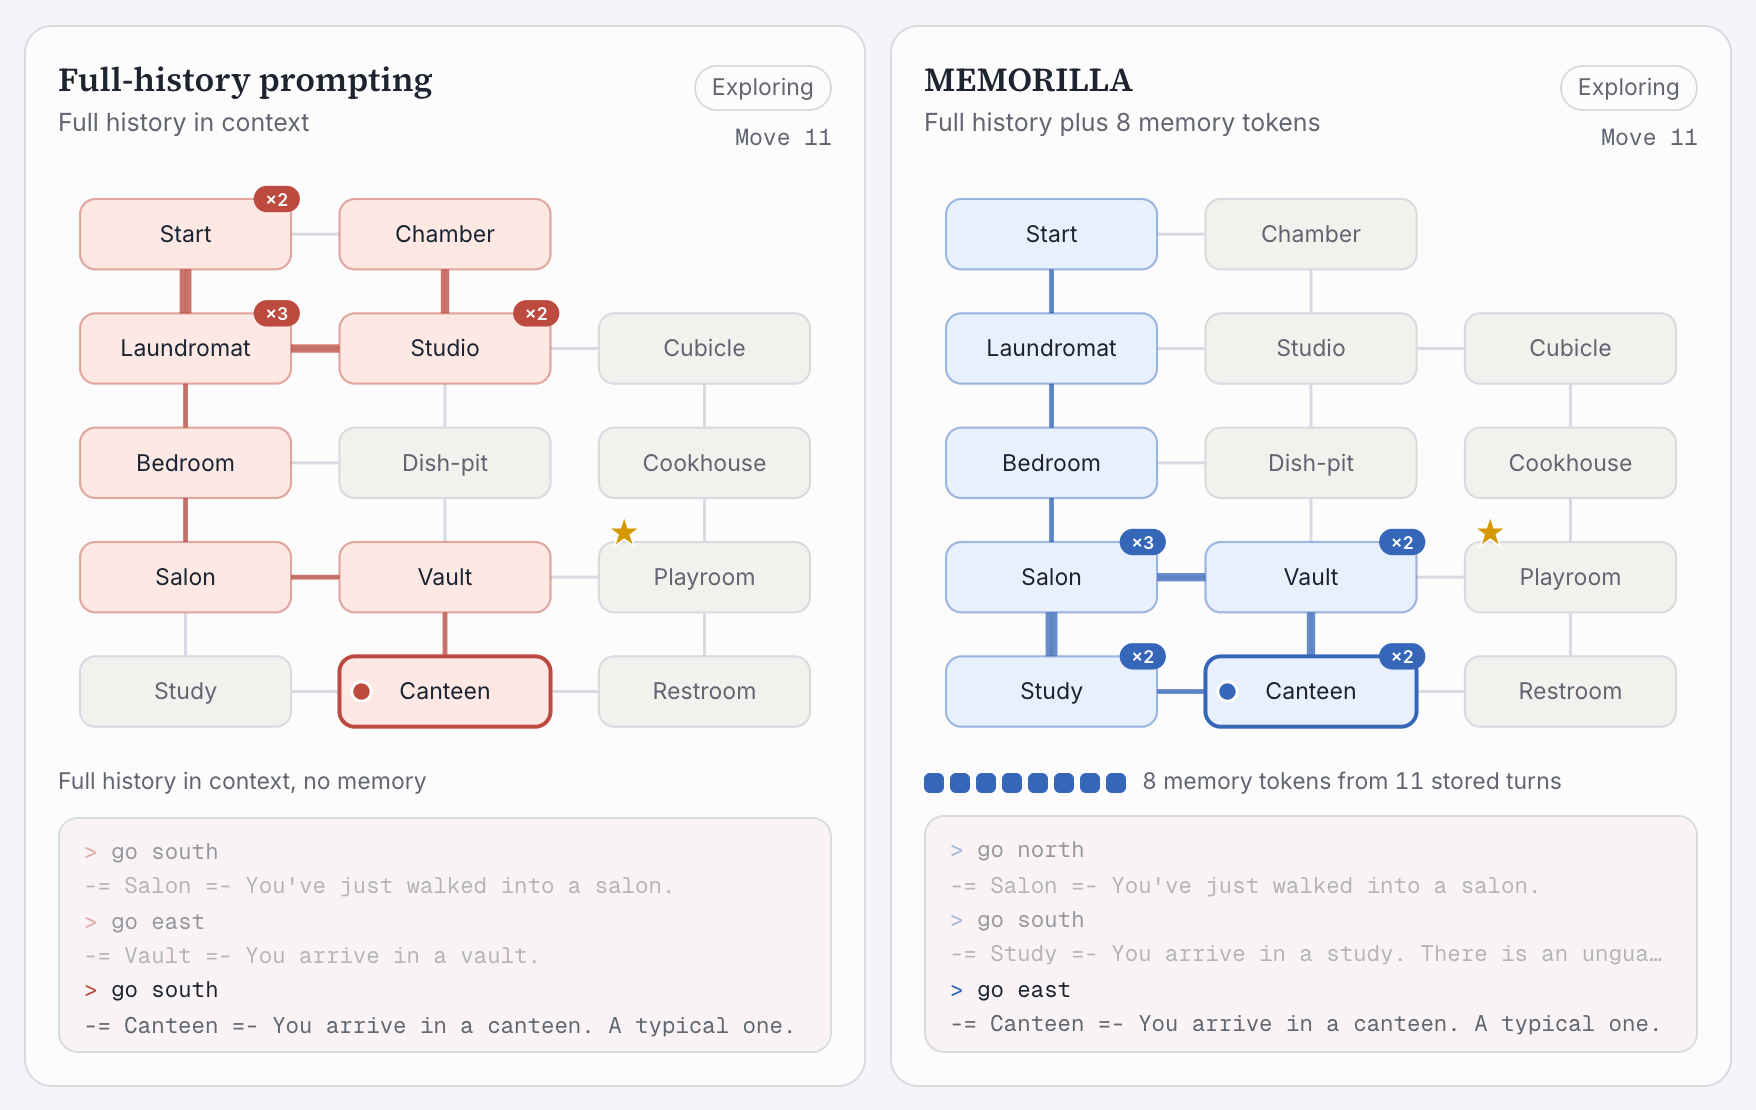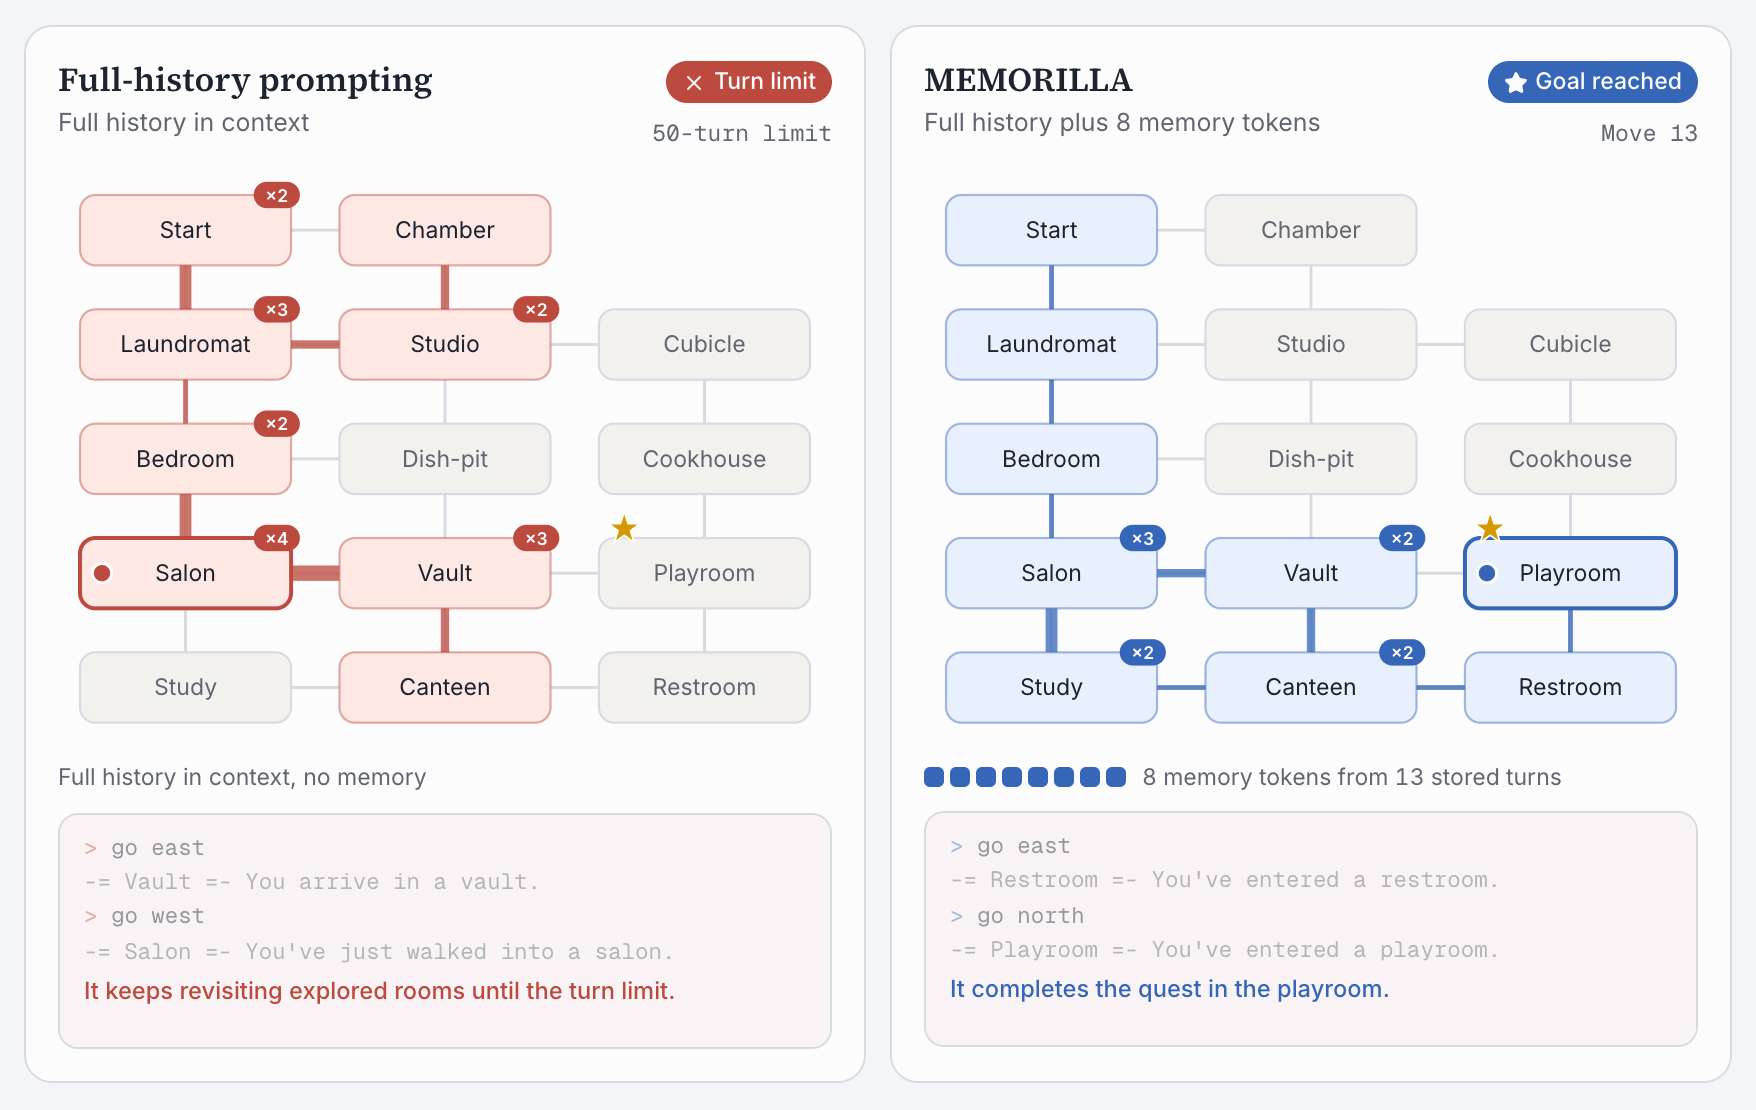
- –The open-source release includes training, evaluation, datasets, and TextWorld reinforcement-learning support.
// TAGS
memorillaagent-memoryraglong-contextembeddingopen-sourceresearch
DISCOVERED
1h ago
2026-10-19
PUBLISHED
1h ago
2026-10-19
RELEVANCE
10/ 10
AUTHOR
Discover AI