OPEN LINK ↗
// 1h agoRESEARCH PAPER
Humanize MLE Agents Shows Fresh Context Wins
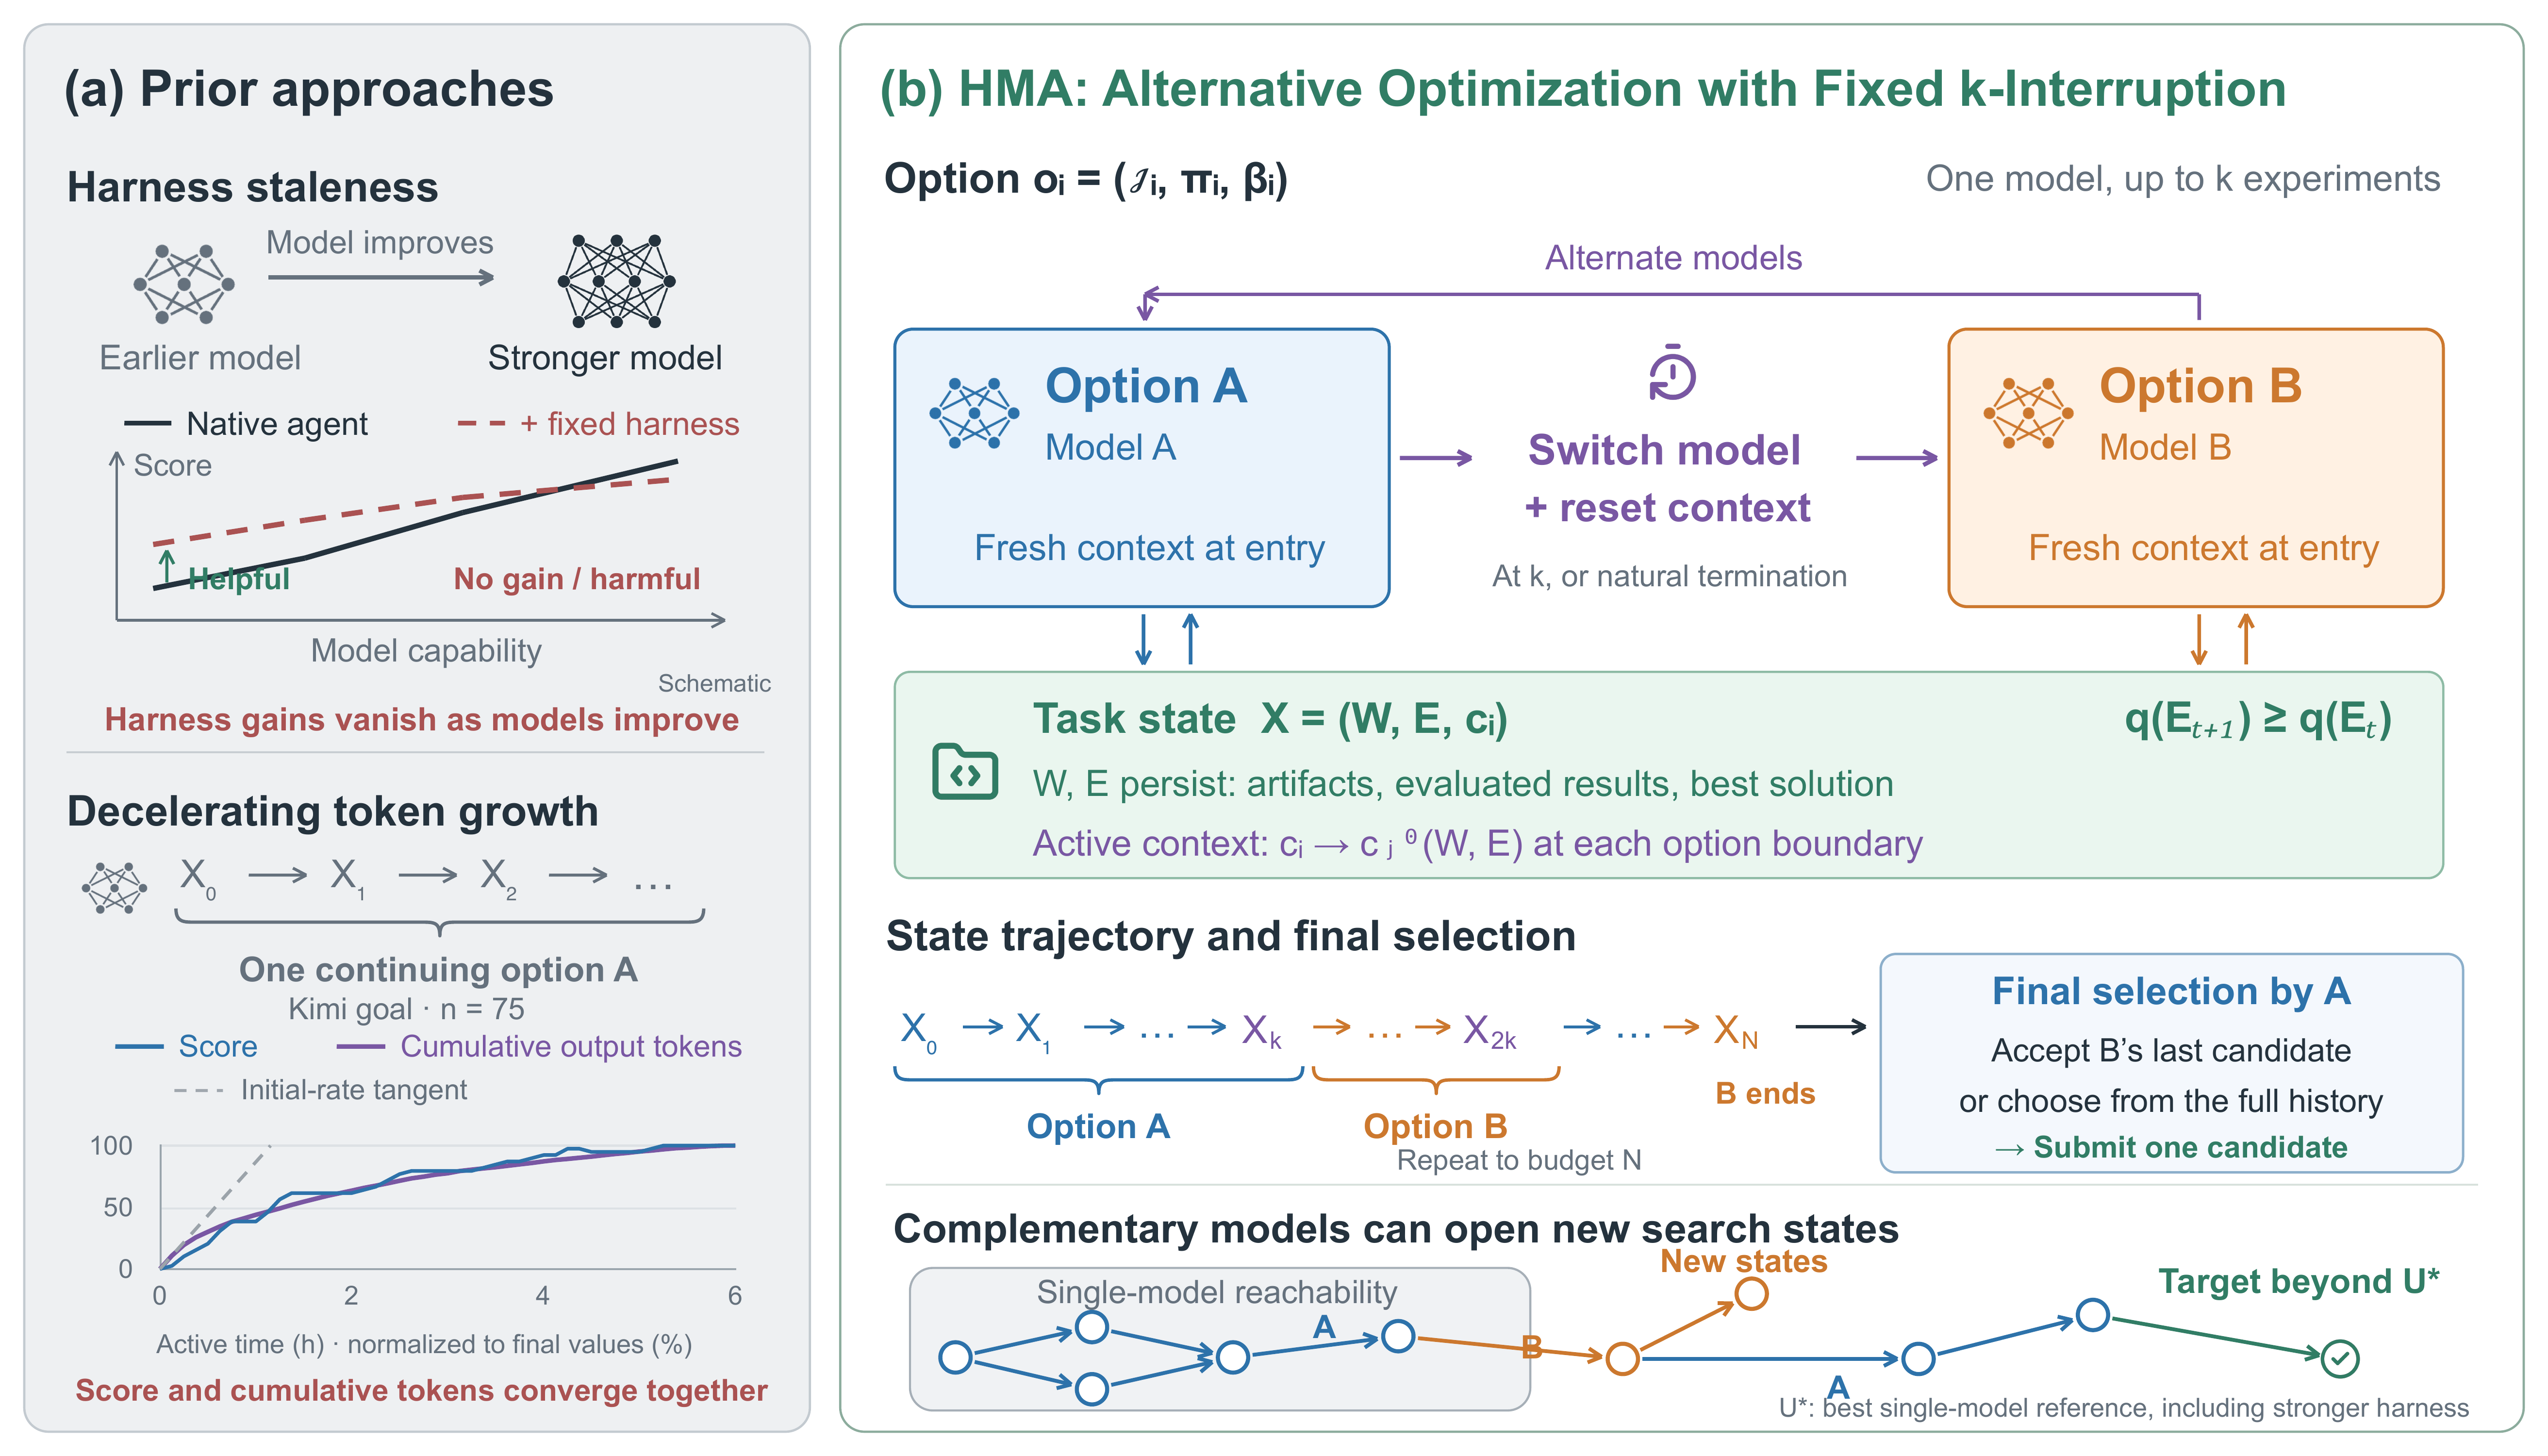
HMA alternates two native coding agents over a shared ML workspace, resetting context after each capped run. Its paper reports a 78.2% any-medal rate across 75 MLE-bench tasks, outperforming either agent alone.
// ANALYSIS
HMA’s strongest idea is operational rather than architectural: disciplined context renewal may beat endlessly extending one agent session.
- –Fresh sessions counter long-horizon reasoning decay while preserving code, experiments, and results
- –The best pairing reached 78.2%, versus 72.4% and 68.0% for the individual agents
- –Agent order matters, with the reverse sequence scoring 4.9 points lower
- –Results are self-reported and have not been reviewed on the official MLE-bench leaderboard
- –The open-source workflow could generalize to software engineering, research automation, and other long-running agent tasks
// TAGS
humanize-mle-agentsai-codingcoding-agentagentcontext-engineeringbenchmarkopen-sourceresearch
DISCOVERED
1h ago
2026-10-13
PUBLISHED
1h ago
2026-10-13
RELEVANCE
9/ 10
AUTHOR
Discover AI