OPEN LINK ↗
// 57m agoOPENSOURCE RELEASE
Open-EmbeddingGemma brings EmbeddingGemma 2 to PyTorch
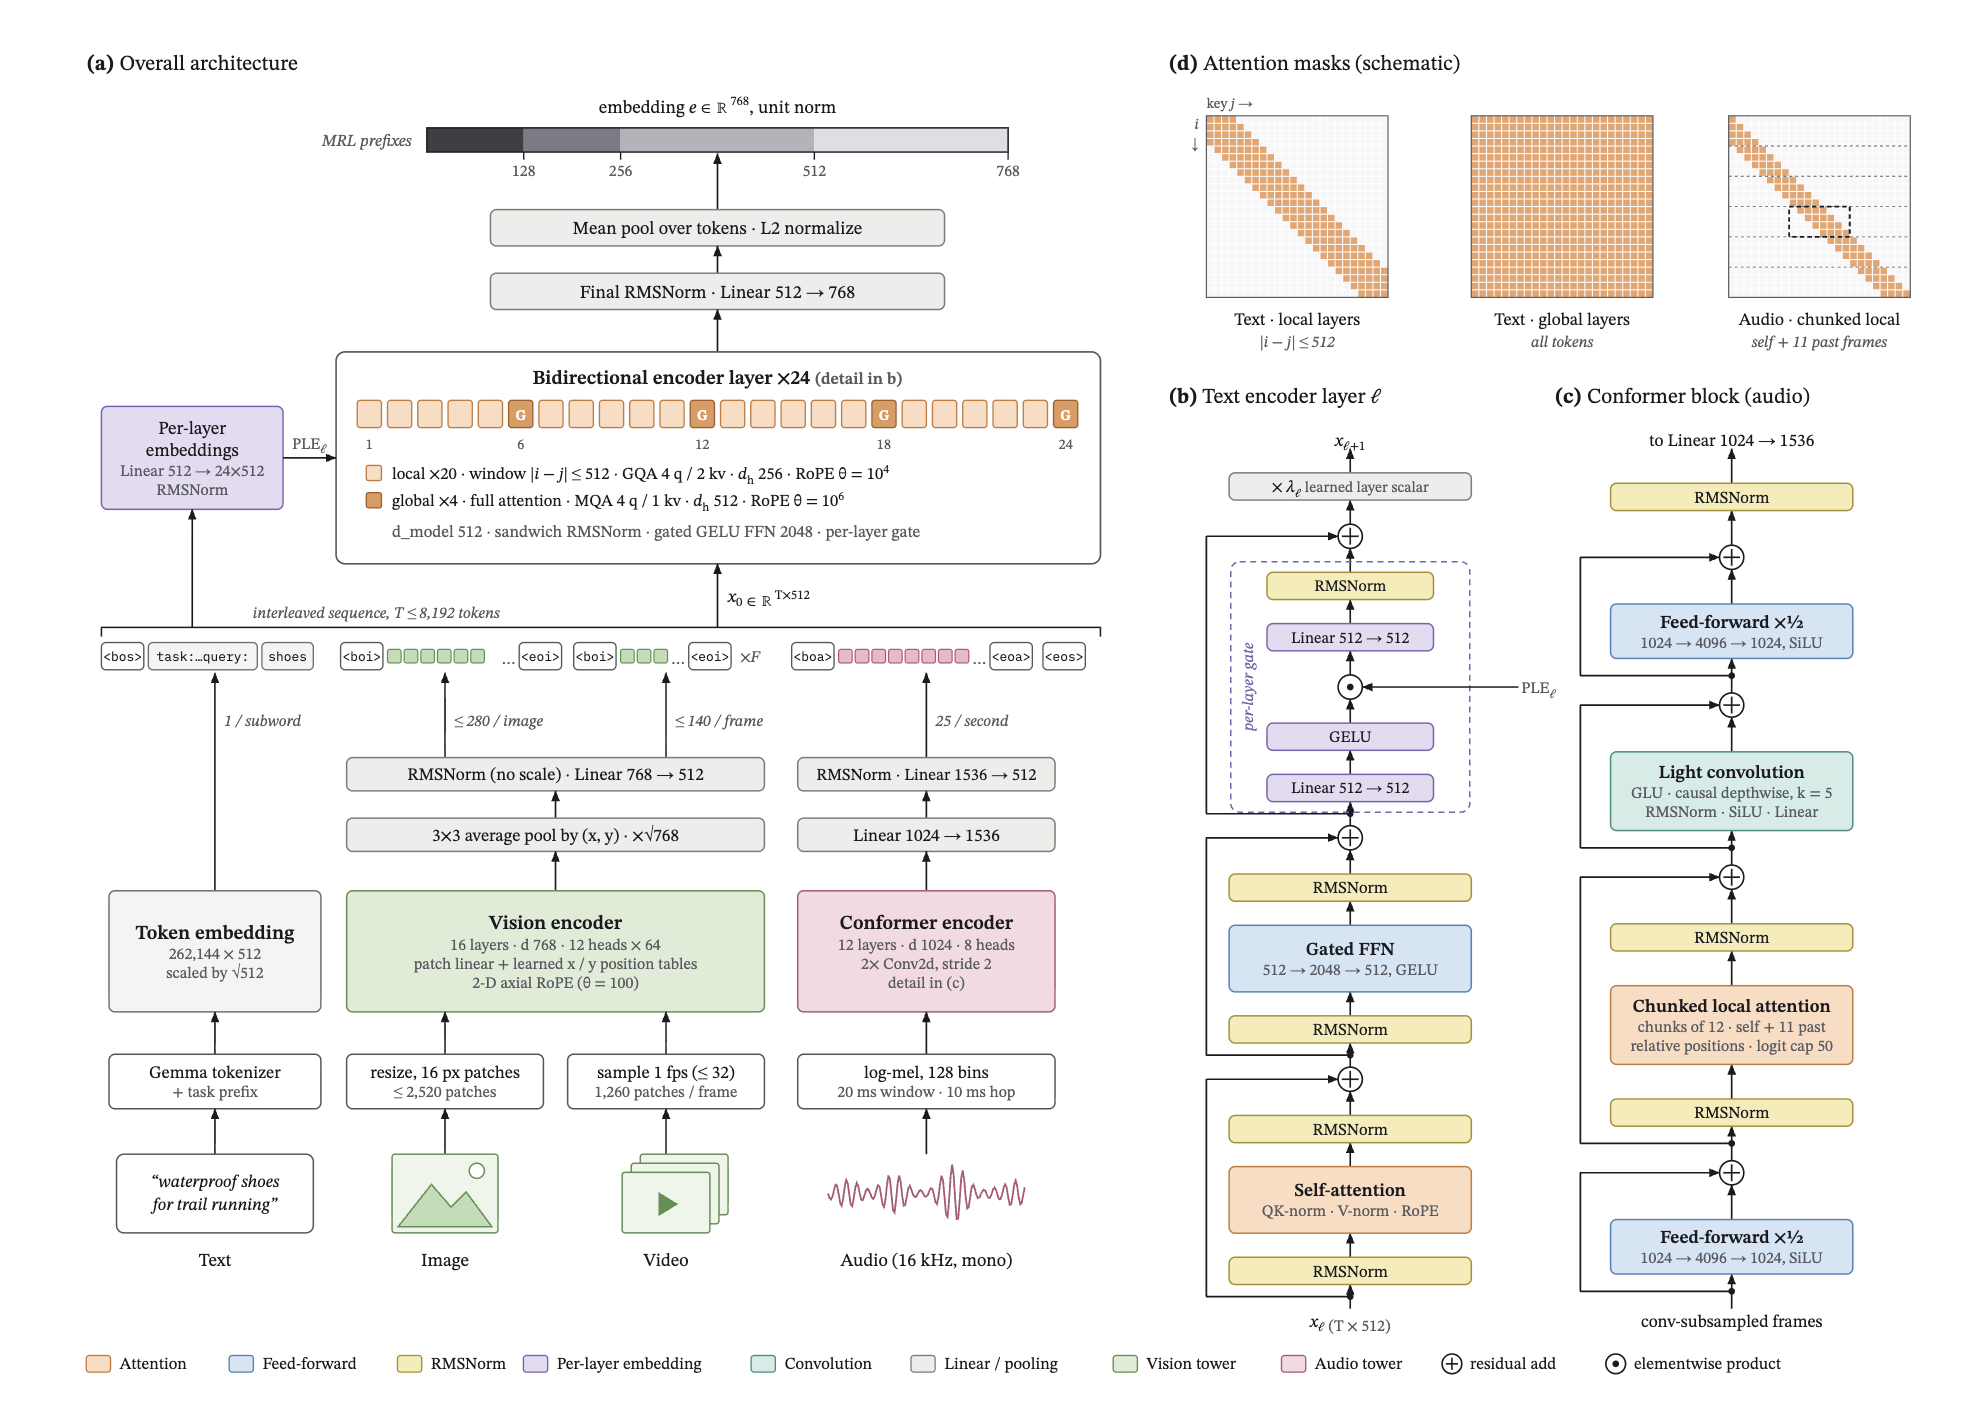
Kye Gomez released a single-file PyTorch implementation of Google’s 740M-parameter EmbeddingGemma 2, supporting text, code, images, video, and audio embeddings. It loads the official weights directly and targets simpler local multimodal retrieval workflows.
// ANALYSIS
This is a valuable implementation release, but calling it a training breakthrough oversells it—the repository currently focuses on inference and leaves training, numerical parity testing, and package distribution on its TODO list.
- –One file mirrors the official model’s parameter names, allowing direct loading of released safetensors without depending on Transformers for the model implementation.
- –The full model maps text, code, images, video, and audio into a shared 768-dimensional embedding space, enabling local cross-modal search and RAG.
- –A text-only configuration reduces the model to roughly 270M parameters, while Matryoshka truncation supports 512-, 256-, and 128-dimensional outputs.
- –The implementation supports 8K-token interleaved multimodal sequences, but requires bfloat16 or float32 because float16 activations overflow.
- –Developers should treat it as an accessible reference and inference stack, not yet a drop-in training framework or polished pip package.
// TAGS
open-embeddinggemmaembeddingmultimodalopen-sourceinferenceragtraining
DISCOVERED
57m ago
2026-10-09
PUBLISHED
1h ago
2026-10-09
RELEVANCE
9/ 10
AUTHOR
popmemecoin