OPEN LINK ↗
// 1h agoRESEARCH PAPER
PURE sharpens 3D reconstruction from unlabeled video
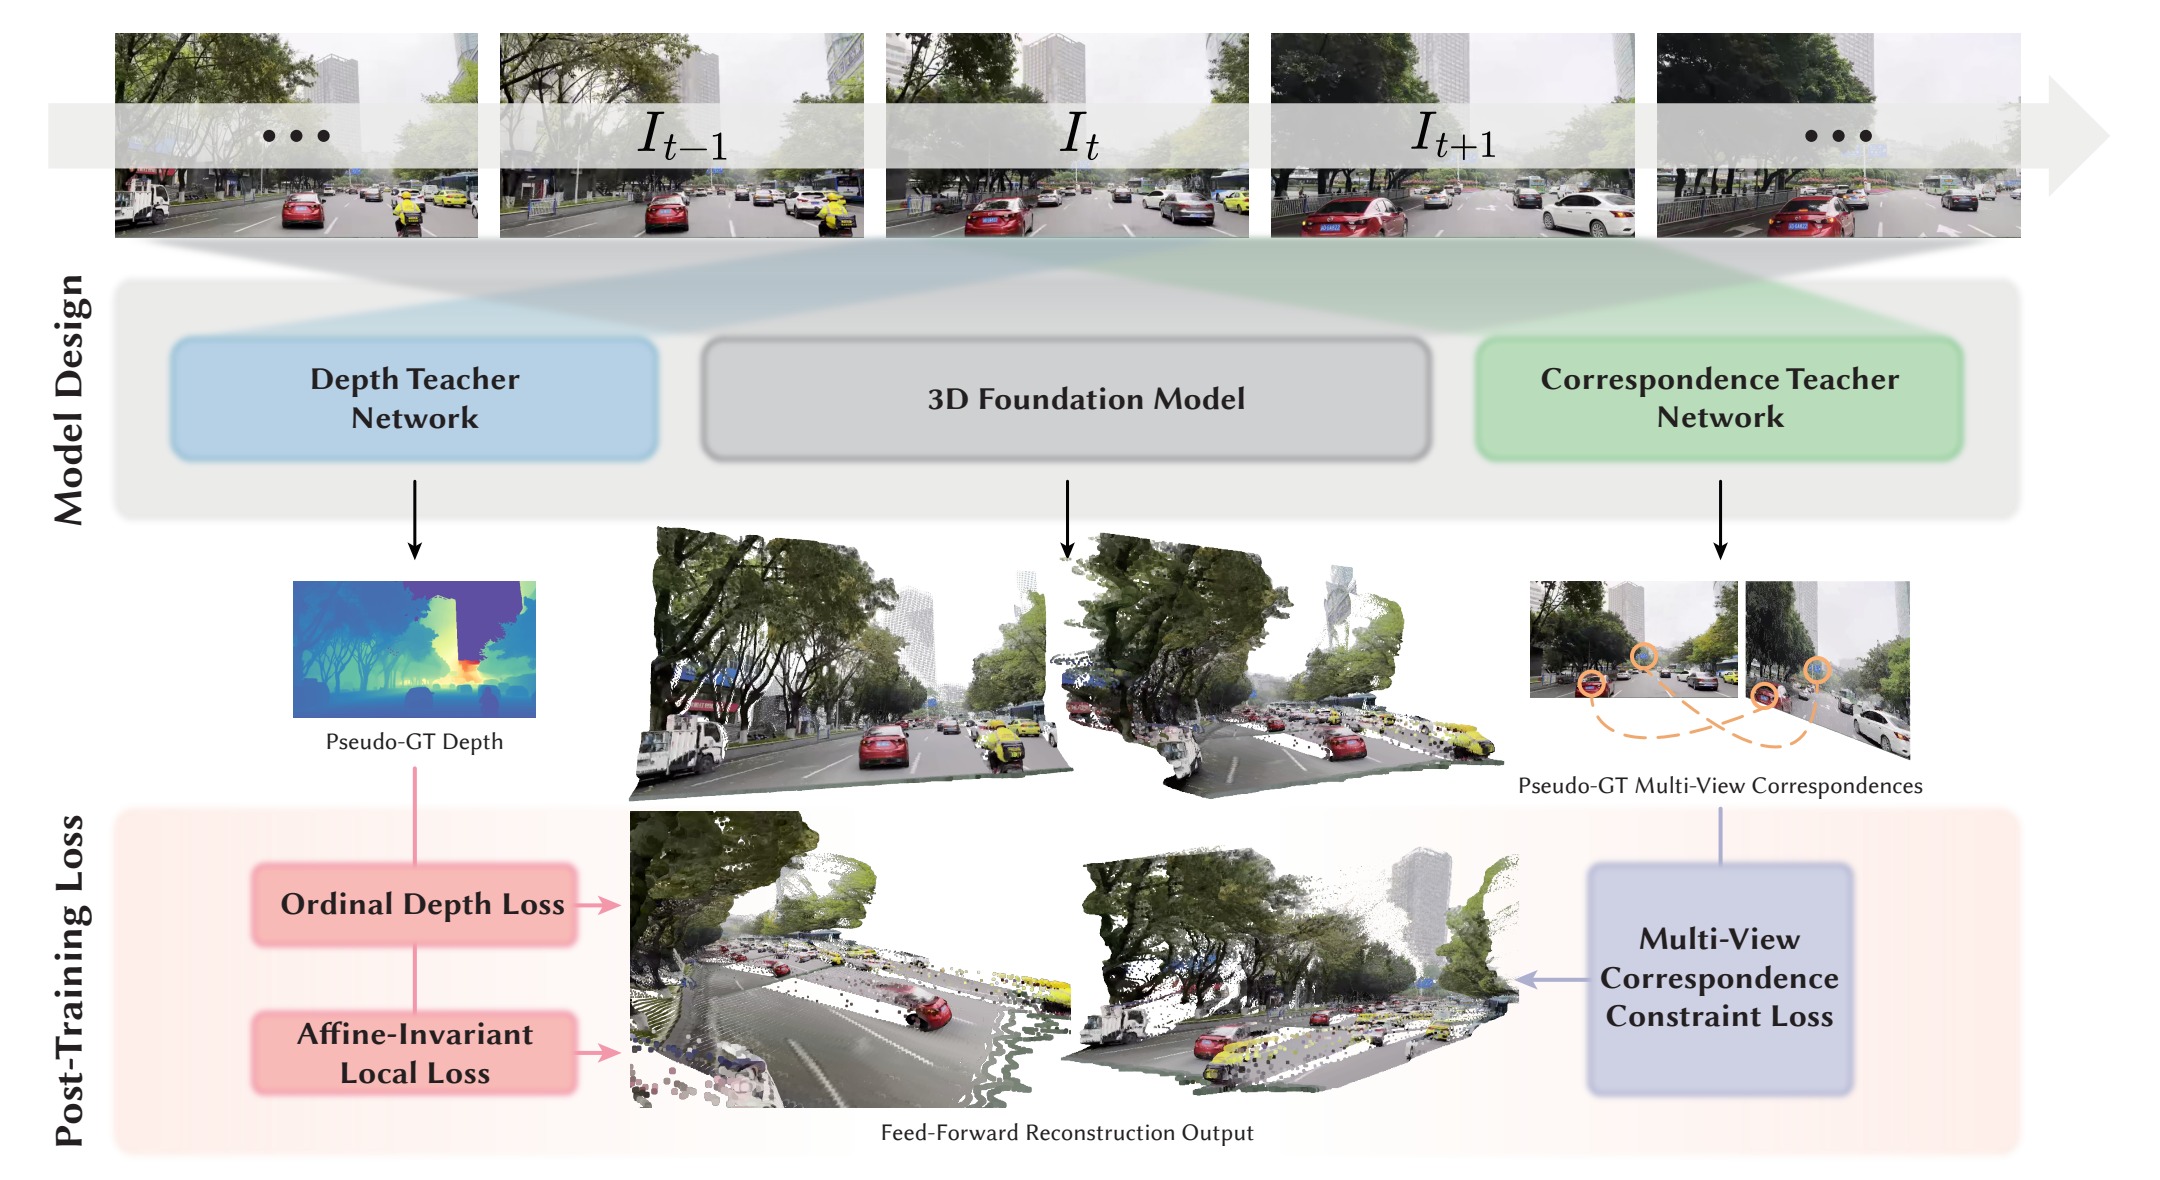
PURE is an annotation-free post-training framework that improves feed-forward 3D reconstruction on dynamic videos without ground-truth 3D labels or test-time optimization. It refines Pi3, Depth Anything 3, and VGGT using geometric cues distilled from existing vision models.
// ANALYSIS
PURE targets the biggest weakness in current feed-forward reconstruction: brittleness around motion, occlusion, and changing illumination. Its practical value lies in adapting proven backbones rather than introducing another heavyweight reconstruction pipeline.
- –Uses relative depth, local geometry, and filtered feature correspondences as pseudo-supervision
- –Trains on millions of real unlabeled frames while mixing synthetic data to reduce catastrophic forgetting
- –Preserves the original models’ inference cost, making deployment more practical
- –Open-source code, weights, and a hosted demo lower the barrier for experimentation
- –Results still depend on teacher-model quality and may retain seams or motion artifacts in difficult scenes
// TAGS
pure3d-genvisiontrainingresearchopen-source
DISCOVERED
1h ago
2026-10-25
PUBLISHED
1h ago
2026-10-25
RELEVANCE
8/ 10
AUTHOR
AI Search