OPEN LINK ↗
// 1h agoRESEARCH PAPER
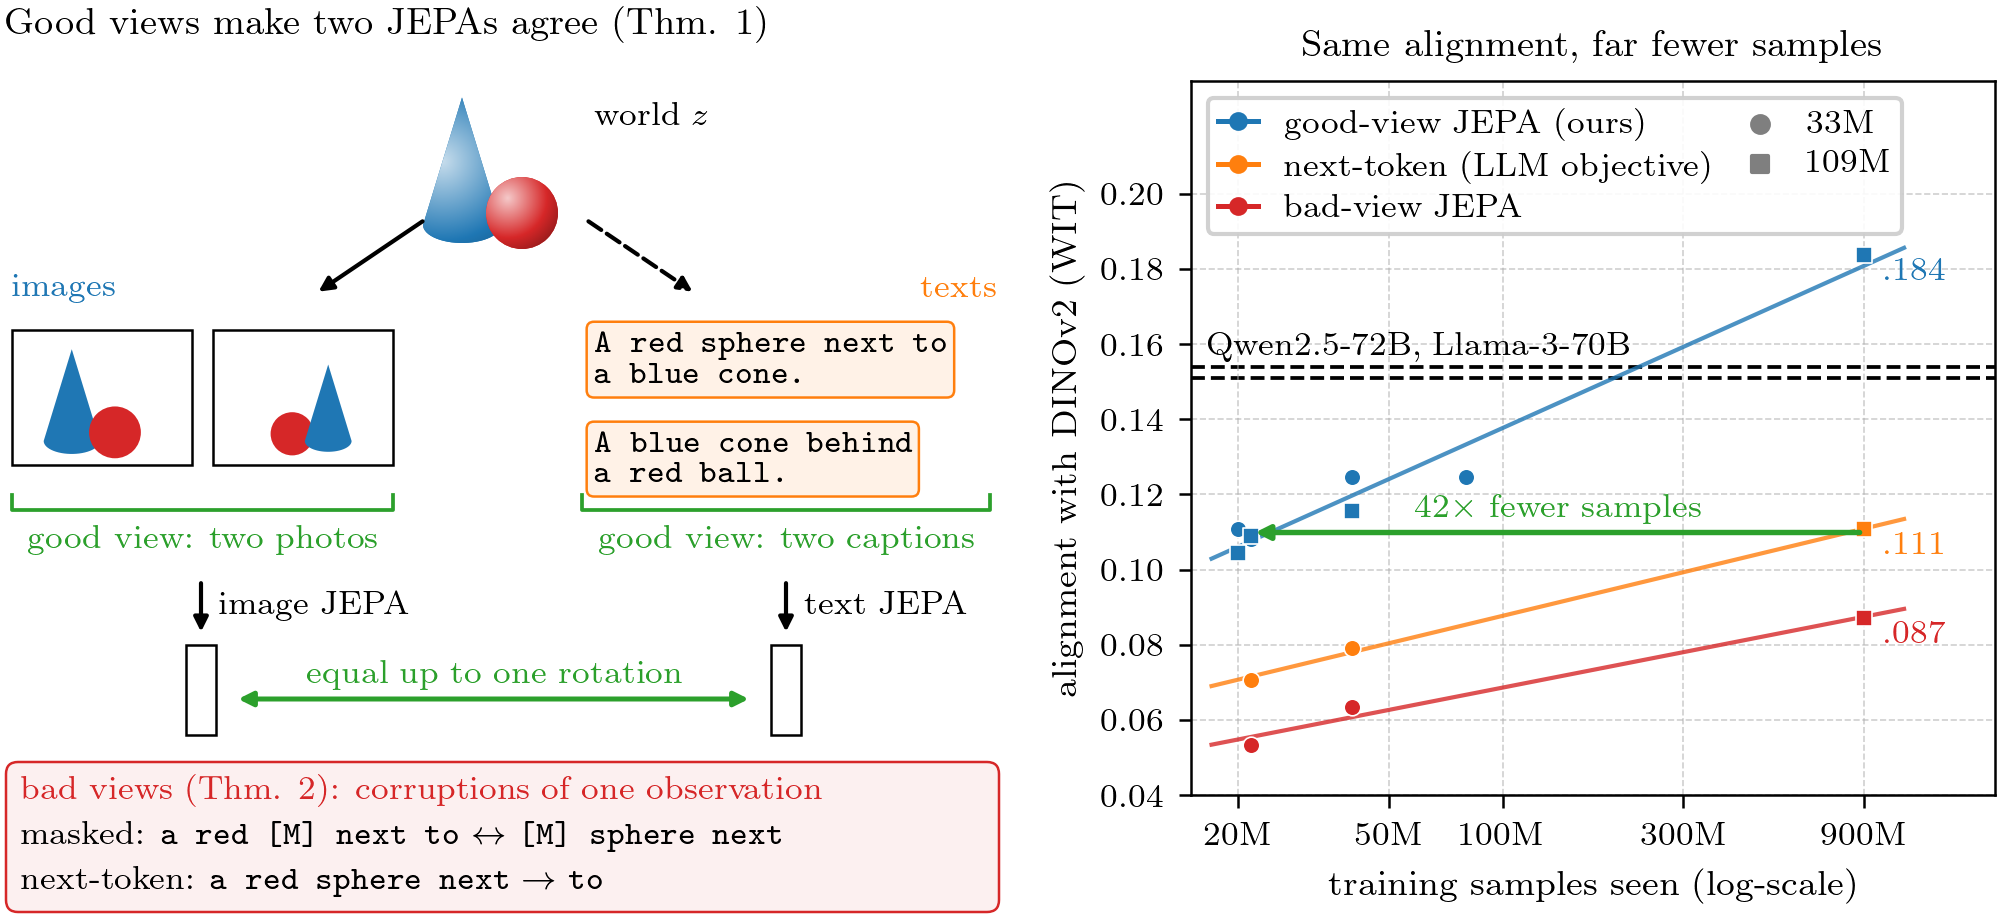
109M JEPA Out-Aligns 72B LLMs
Randall Balestriero and Yann LeCun’s paper reports that a 109M-parameter text JEPA aligned more closely with DINOv2 and CLIP image encoders than tested language models up to 72B parameters. The result targets representation alignment—not general language or reasoning performance.
// ANALYSIS
This is a sharp argument that training objectives and data pairings can matter more than brute-force scale for multimodal representations.
- –The JEPA reached comparable alignment using 42× fewer training samples than next-token prediction.
- –The comparison measures shared embedding structure, not whether the small model is a better chatbot or problem solver.
- –The authors’ theorem depends on idealized assumptions, while the experiments are from a fresh, non-peer-reviewed preprint.
- –The [MIT-licensed code](https://github.com/galilai-group/prh-proof) and reproducibility logs make this unusually testable, but independent replication remains important.
- –If the result holds, specialized representation models could become far cheaper building blocks for vision-language systems.
// TAGS
text-jepasmall-llmllmembeddingmultimodalbenchmarkresearchopen-source
DISCOVERED
1h ago
2026-11-02
PUBLISHED
2h ago
2026-11-02
RELEVANCE
9/ 10
AUTHOR
simplifyinAI